
I get in where I fit in.
Track record
Real numbers, not vibes.
$3.1M+
saved through a payroll analytics redesign at Teamshares
6x
increase in design-system adoption after migrating Marketo to Adobe's Sky system
33%
faster time-to-resource after redesigning Meroxa's core workflow, measured in usability testing
~60%
production-ready fidelity reached out of the gate with an AI-assisted workflow at Vye Health
Case studies
The work behind the numbers.
Five write-ups, from the brief to what shipped. Pick one to read it here.

What I do
You don't always need a full-time Head of Design.
Sometimes you need someone senior enough to lead the function, experienced enough to see what's wrong, and hands-on enough to actually fix it. That's where I come in.
Who I help
Maybe you don't need more designers. You might need more design leadership.
How I work
Part-time leadership. Full-time commitment to the work.
I embed with your team rather than operating from the sidelines. I work directly with founders, Product, Engineering, and Design to understand what's getting in the way, establish priorities, and move the work forward.
The process
The process is a "we" thing.
-
01
Understand
I start with the product, the business, the customers, and the people doing the work.
-
02
Align
We identify what's actually worth solving and get Product, Engineering, and Design working from the same understanding.
-
03
Build
We establish the workflows, systems, and design direction needed to move faster without creating more chaos.
-
04
Ship
I stay close to the work and help turn decisions into products your team can actually build.
-
05
Scale
The goal isn't to make you dependent on me. It's to leave your team more capable than when I arrived.
Let's work together
Need design leadership? Let's talk.
Tell me where your team is today, what's getting in the way, and where you're trying to go. If I can help, we'll figure out what that looks like.
Start a conversation- 1.5 hrs end-to-end workflow, down from 3
- 135 hrs saved per cycle across six leads
- $3.1M annual efficiency gains
01What industry leads actually do
Teamshares acquires small businesses, then hands the reins to new presidents — often first-time operators without an MBA or an ops background. Each president gets a company, and Teamshares expects industry leads to make sure the wiring underneath doesn't fail.
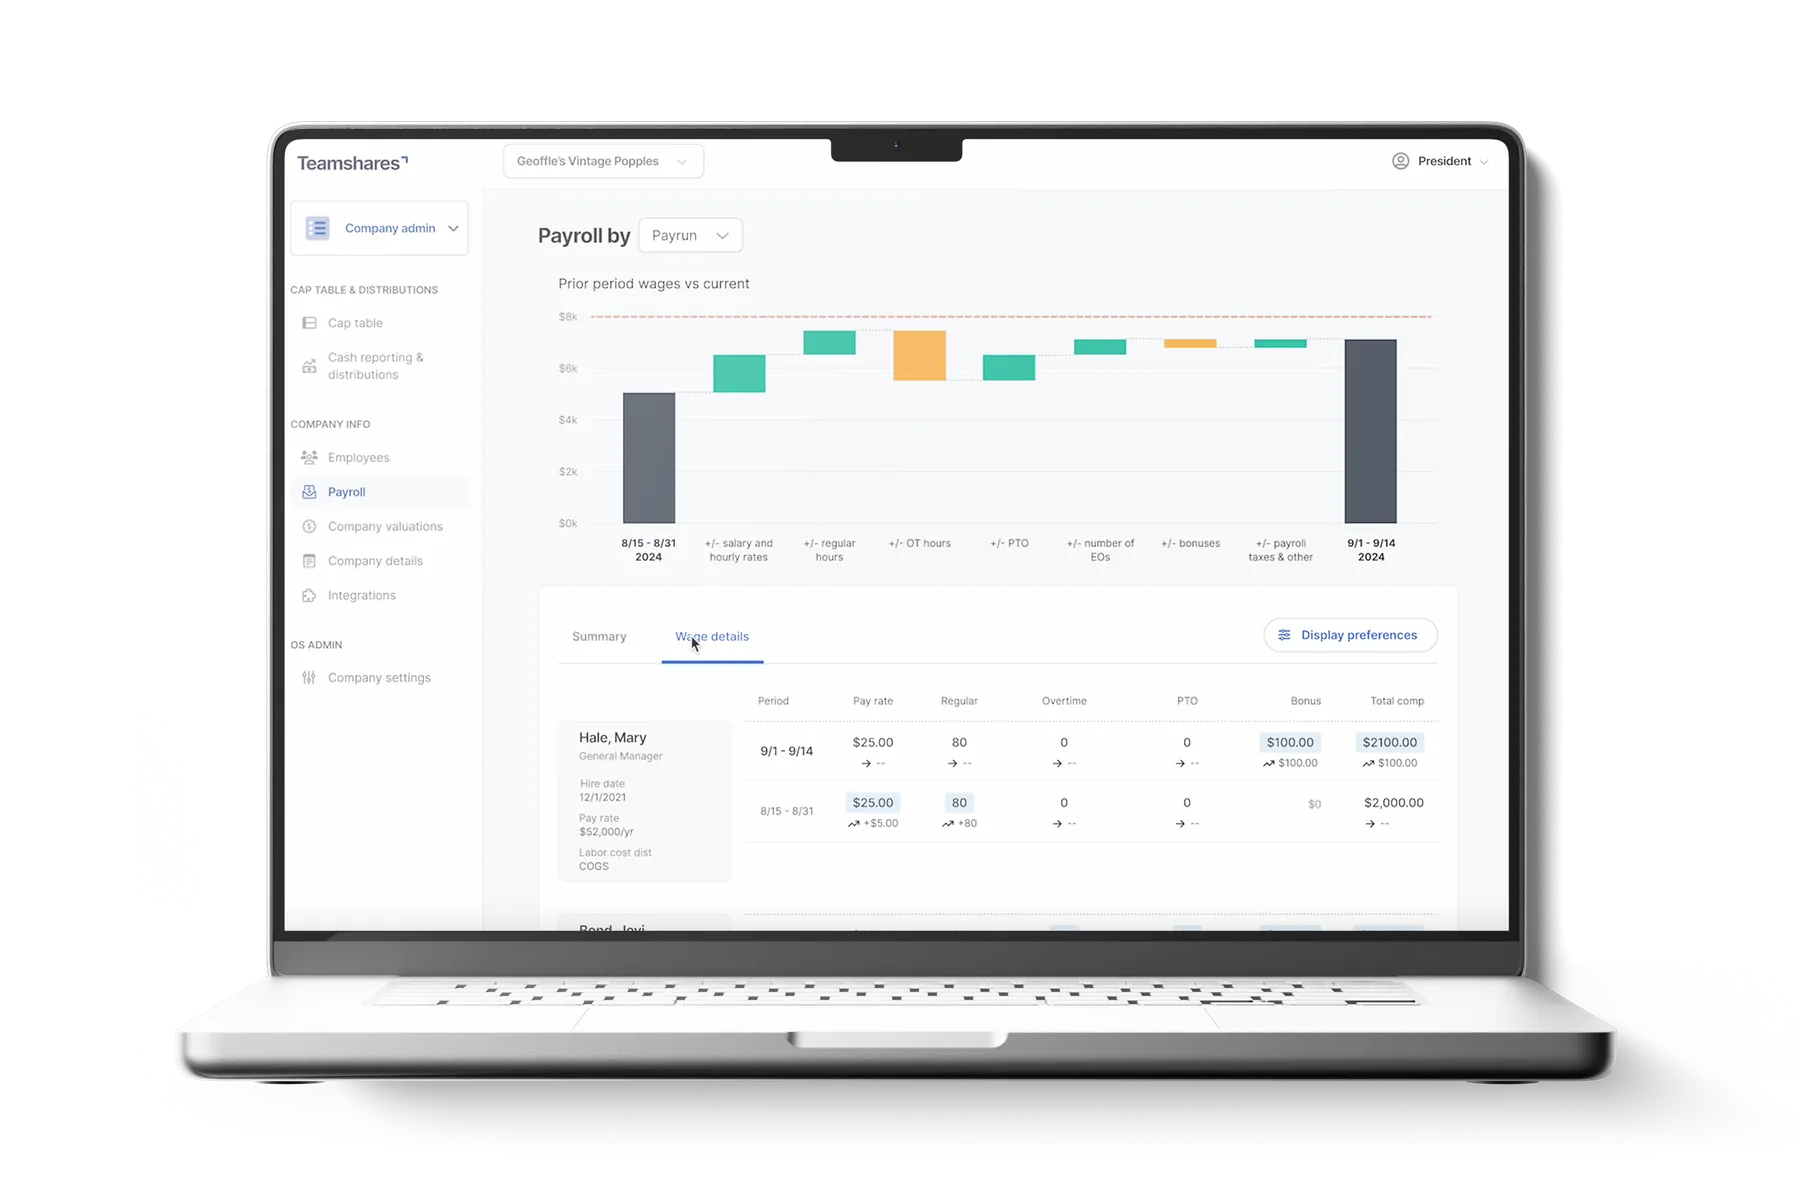
The ask made sense on paper: give industry leads a place to view payroll data and generate reports. But the framing assumed the problem was display. It wasn't.
02What discovery actually found
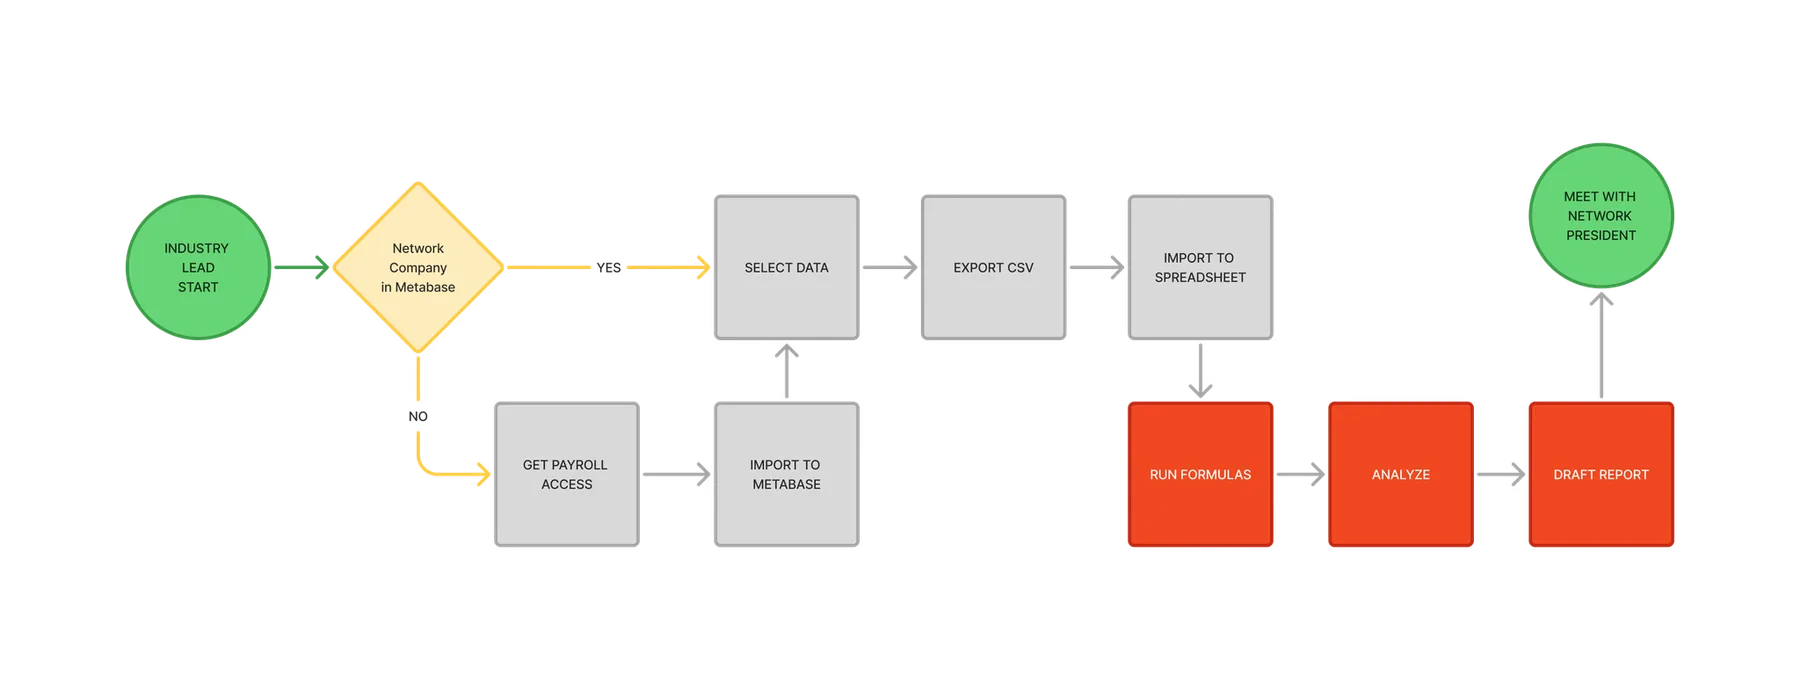
Before opening Figma, I spent time with the leads — shadowing their workflow, watching how they built payroll lists they already used, learning the vocabulary. What I found: three hours of manual prep before every conversation that mattered.
"How do we display payroll data" became "How do we get leads straight to analysis — and straight to the conversation?" That's a fundamentally different product. The second one is a workflow that happens to display data. Every decision came from that distinction.
03What the leads actually needed to see
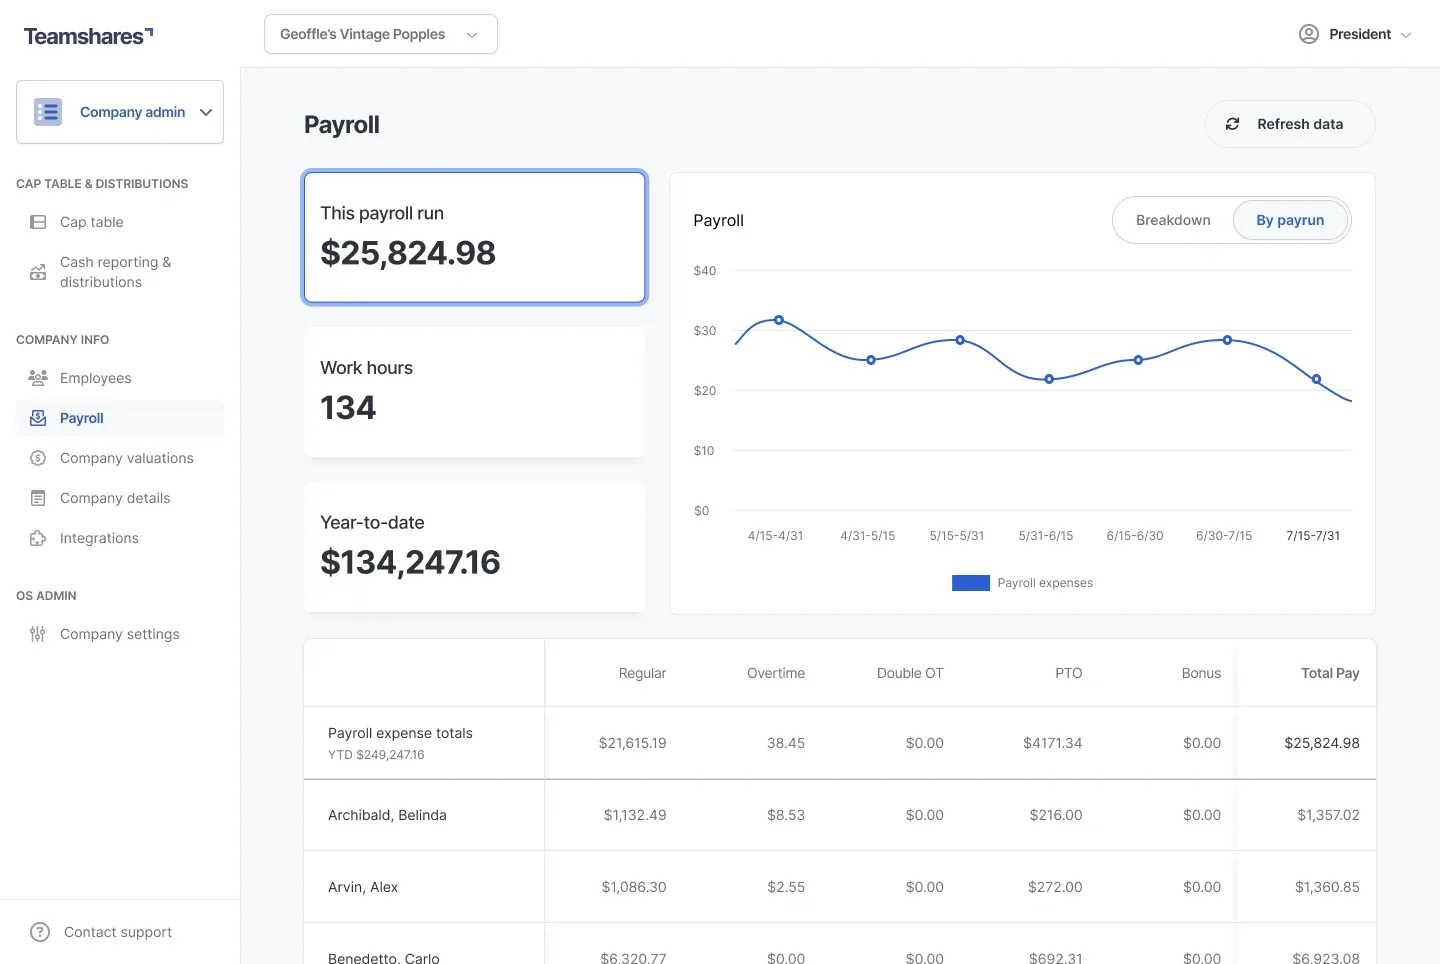
I did a full walkthrough of how leads did analysis in their spreadsheets before the dashboard existed. Period-over-period comparisons. Changes in overtime, PTO, headcount — laid out so they could spot the story at a glance, without doing math first.
The key insight: leads needed comparative data. Prior period vs. current. The delta mattered more than the number. A payroll run showing $180K in overtime means nothing in isolation. A payroll run showing overtime up 40% from the prior period is a conversation starter.
Once I understood that the job was spotting change, the information hierarchy became clear. Deltas go at the top. Raw figures support them, not the other way around. That distinction flows all the way down to Metabase and the component design.
I found a charting library that could replicate the waterfall and period-over-period views leads were already building by hand. Meeting them in their existing mental model meant zero re-learning and faster adoption from a pilot group that didn't have time for a learning curve.
04The integration scope problem
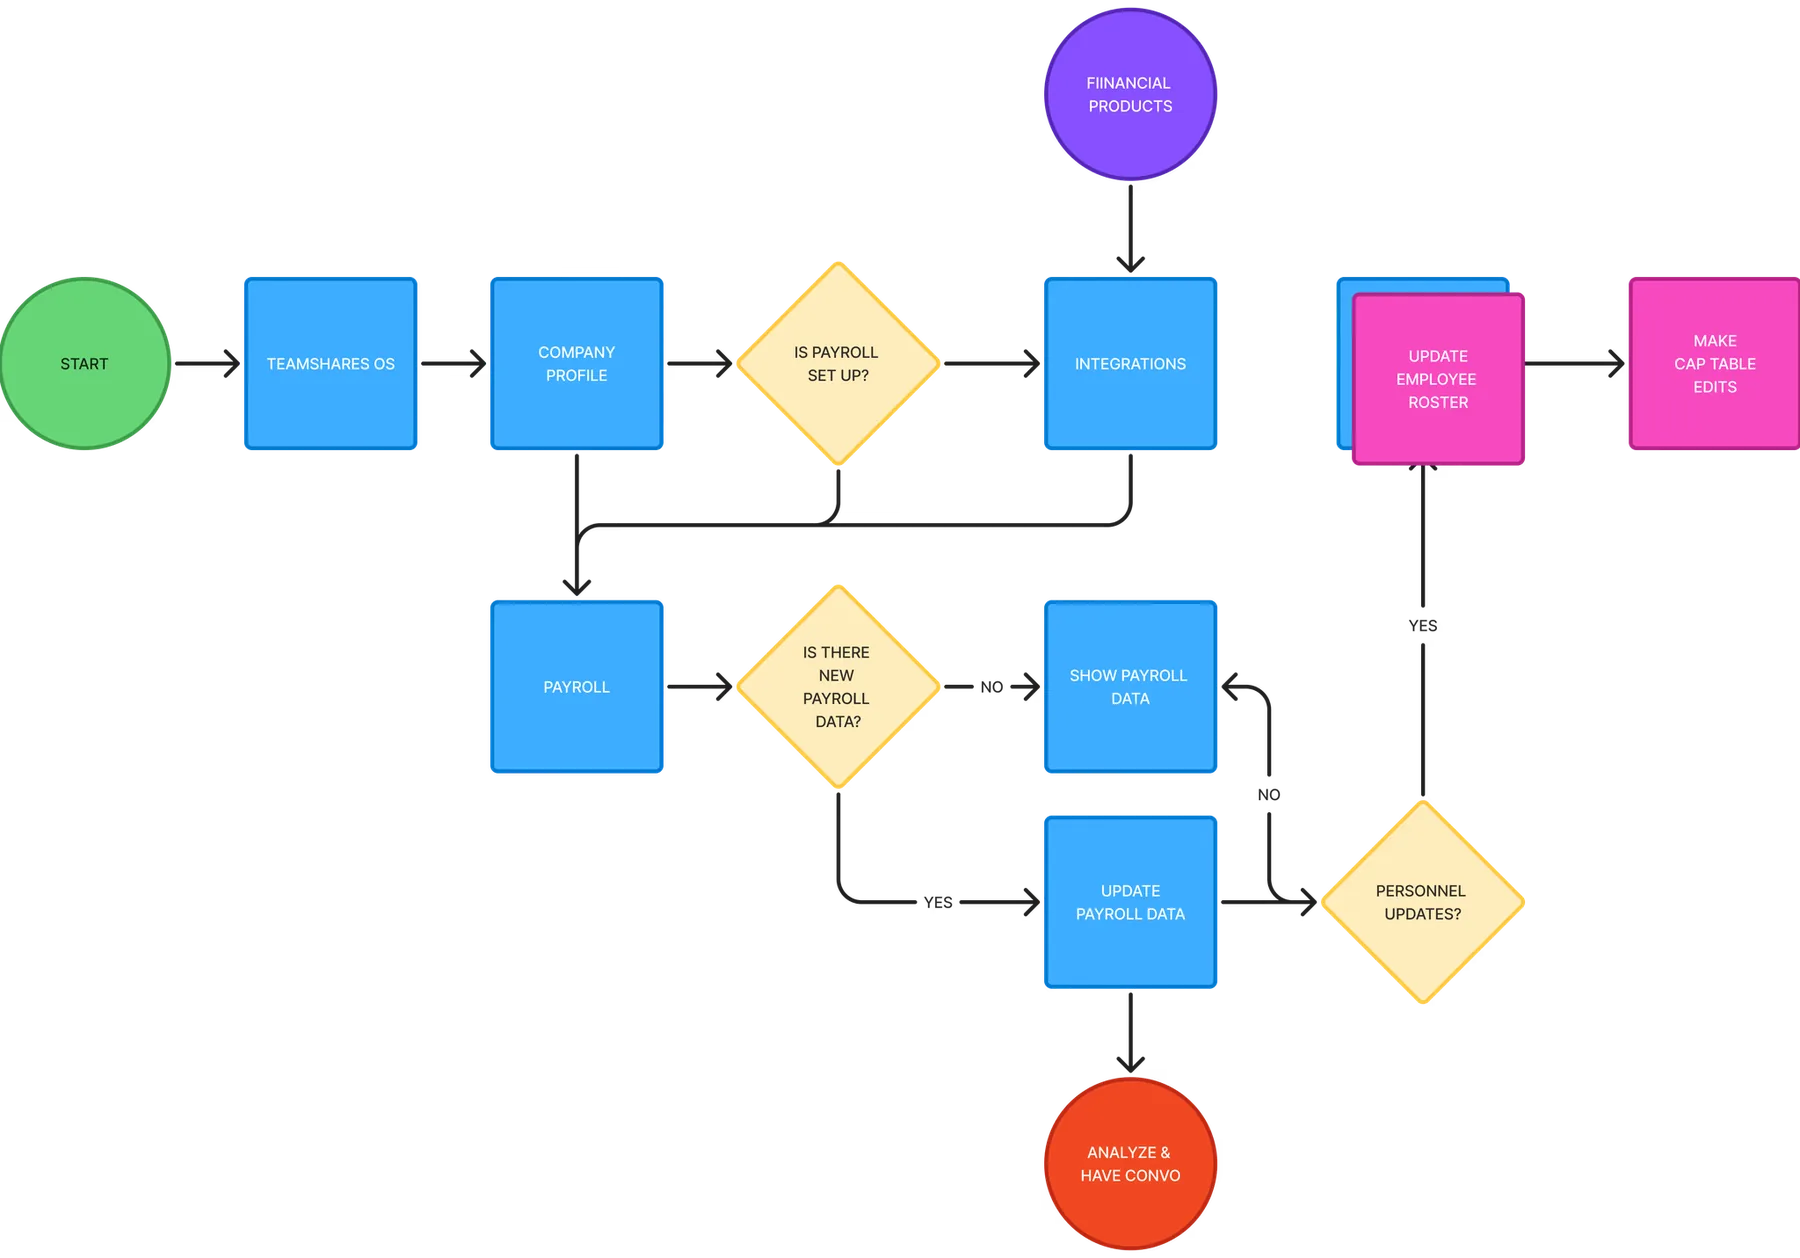
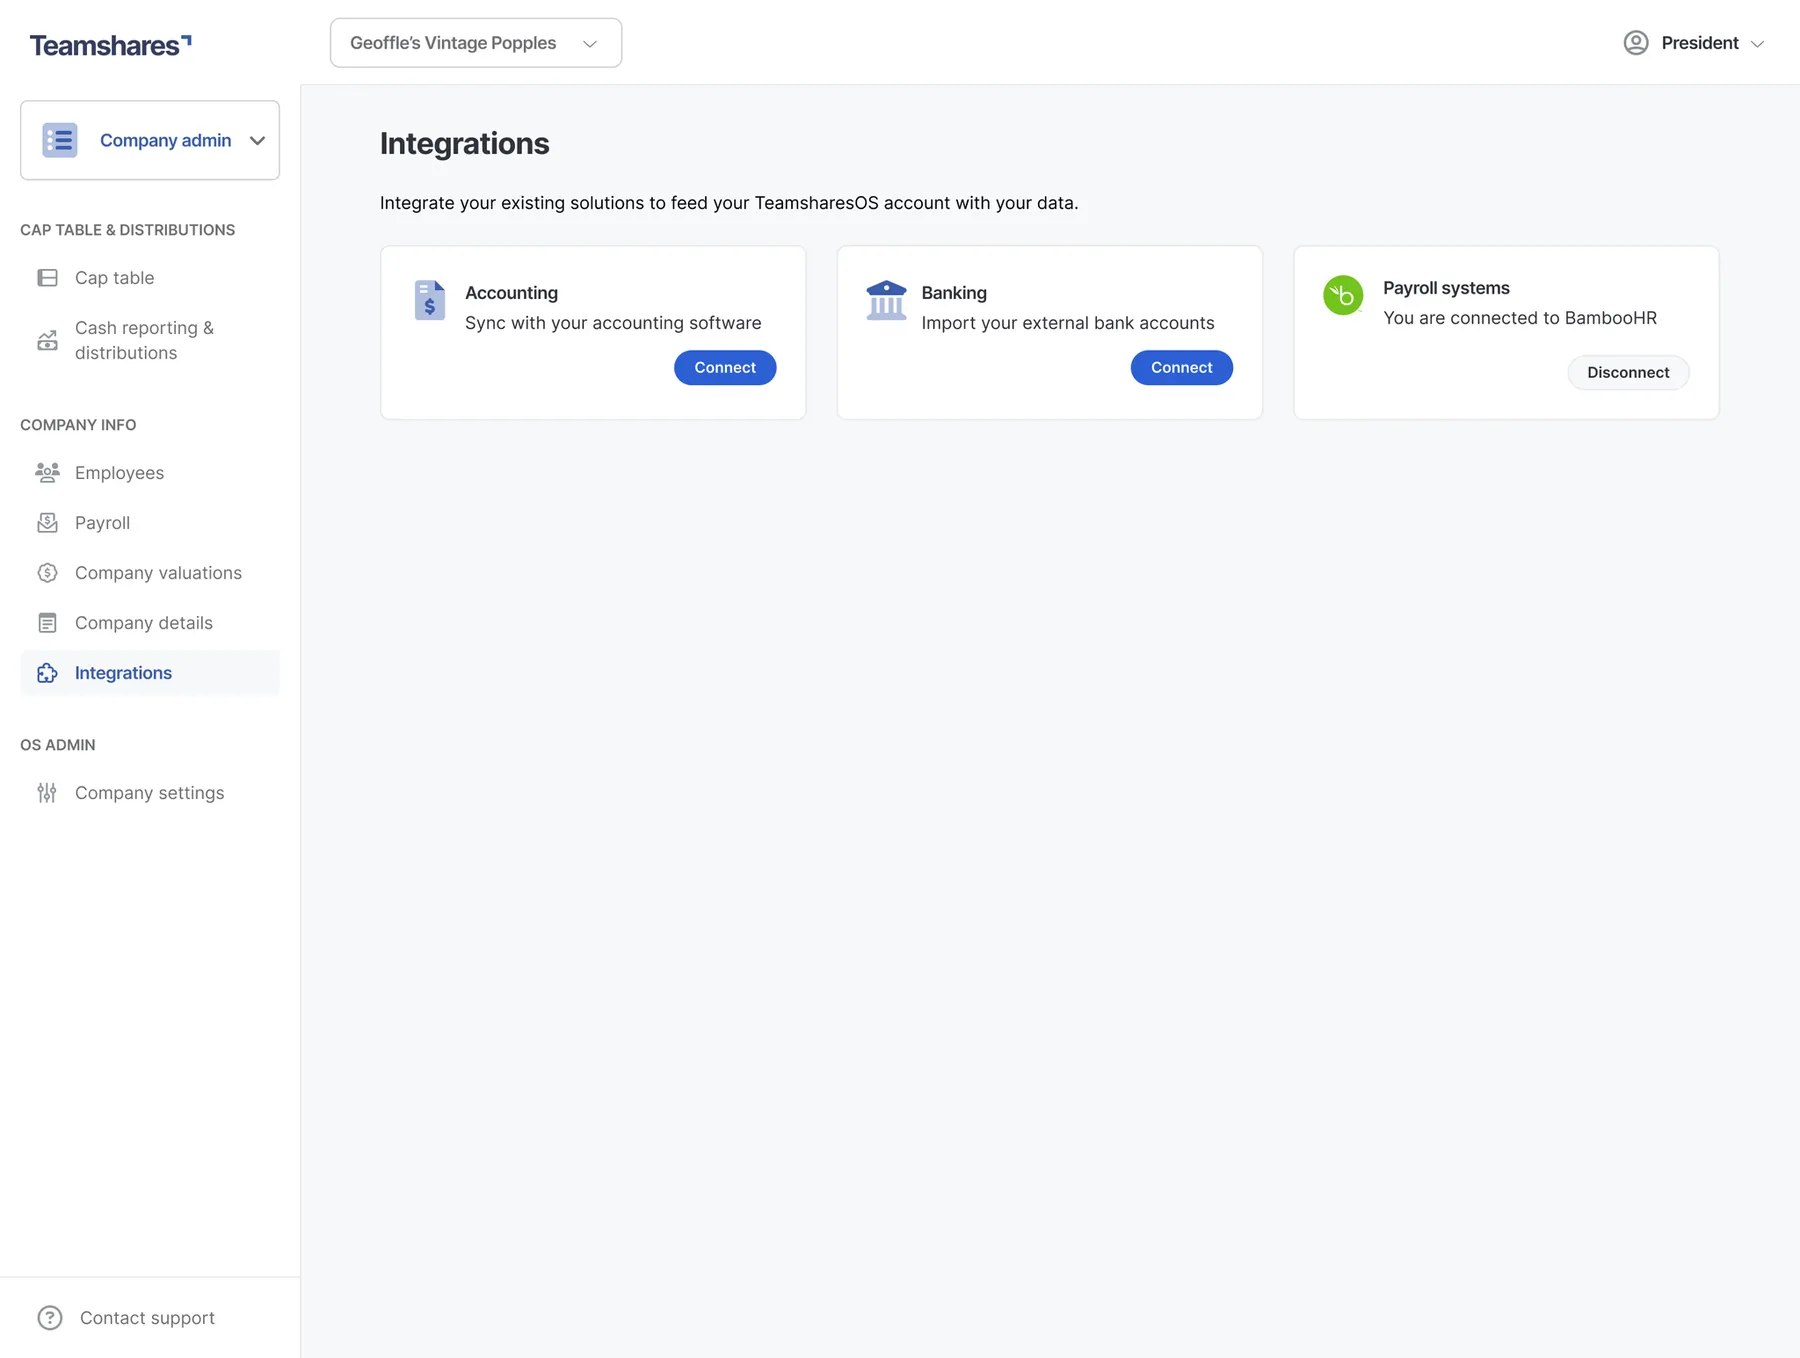
Payroll data at Teamshares doesn't live in one place. Ninety-plus network companies running everything from Gusto to ADP to Paychex to BambooHR. Disparate systems, disparate export formats, a lot of manual process stitching it together.
We used Merge for implementation — it let us move fast against a fragmented vendor landscape without building bespoke connectors for every payroll system. The tradeoff was a dependency on a third-party integration layer. The alternative was more internal engineering work for every new payroll system added to the network. Given that Teamshares was acquiring companies constantly, the Merge dependency was the right bet.
05Designing for the platform
Once the integrations were in place, payroll data was live and structured inside Teamshares for the first time. I pushed hard to design the integration layer to serve the full platform beyond the industry leads workflow.
The argument I made internally: the integration work is the expensive part. Building it for one workflow and then rebuilding it for three more is three times the cost for the same outcome. Do it once, do it right, and let the whole platform inherit it.
 Platform-wide cascade
 Integration hub
06The concession: anomaly detection vs. delta highlighting
The vision I wanted to ship was anomaly detection — a dashboard that could flag unusual patterns automatically before a lead even opened the screen. The problem was data maturity. The integrations were brand new. There was no historical baseline to define what "normal" looked like for any given company.
The delta highlighting was the right call given the constraint. But I made a mistake in how I reasoned about it: I let the ideal version crowd out a good-enough intermediate. A simple threshold-based alert — flag any payroll run that's 20% or more above the prior period — doesn't require historical patterns, just a rule. That was buildable from day one and I didn't push for it. The lesson I've carried since: the right question isn't "can we ship the full vision?" It's "what's the best version of this we can ship now, given what we actually have?"
07What the outcomes actually mean
08What I'd do differently
The threshold-based alert is the obvious one. Letting the full anomaly detection vision crowd out a simpler, shippable version was a failure of prioritization that I owned.
The other thing: I'd push earlier and harder for the platform scope. The argument that the integration layer should serve the full platform rather than just the leads workflow landed eventually, but it landed mid-build rather than at the start of scoping. Some architectural decisions had already been made with a narrower surface in mind. That conversation needed to happen before the first design review.
Every Teamshares network company is a small business with real employees who took a bet on employee ownership. The industry lead's job is to make sure that bet pays off. If they're spending half their day doing spreadsheet prep, they're not doing their job — and the companies they're responsible for are getting less of what they need. The dashboard was bigger than productivity — it was a lever on a model that matters. Getting the framing right at the start was what made everything else possible.
Teamshares is a private company. Screens shown are representative of shipped work.
- 20+ leaders placed through the platform
- 10+ qualified leaders benched for future placement
- 1 source of truth, replacing Lever and spreadsheets entirely
01Why this wasn't an ATS problem
The brief was straightforward: build an applicant tracking system to replace the spreadsheet the recruiting team was running on. But a few conversations in, it was obvious that a better tracker wasn't going to solve what was actually broken.
Teamshares' business model is specific. They acquire small businesses, transition them to employee ownership, and install a President to run each one. That President placement is the unlock. Without the right person in place, the whole model stalls. And executive hiring takes 2 to 6 months on average — which meant every open President slot was a company sitting in limbo.
They had 80+ companies acquired. Some Presidents were running two companies at once just to cover gaps. The spreadsheet wasn't failing because spreadsheets are bad. It was failing because nobody had designed for what recruiting at this volume and this stakes level actually required.
The team was thinking: "How do we track candidates better?" The right question was: "How do we build a talent pipeline that ensures Teamshares always has qualified leaders ready to place?" A candidate tracker optimizes individual hires. A talent pipeline is infrastructure that compounds over time. I pushed for the second framing before a single screen was designed.
"A knack for turning complex problems into clear, user-friendly solutions, always keeping the user's needs at the forefront."
Kevin Rikio Shiiba · Co-founder & CTO, Teamshares
02What discovery actually looked like
Discovery here wasn't just recruiter interviews. It was mapping the entire operating model: how acquisitions flowed, how President slots opened, how candidates moved through the process, and what happened to the ones who didn't get placed. That last part mattered more than anyone had thought to document.
03The hardest design work happened before Figma opened
Before I touched any UI, I mapped every state a candidate could be in across the full lifecycle — not just the happy path, but every edge case I could find. What happens when someone gets placed but the company folds six months later? What happens to a finalist who didn't get the offer? What happens when a placed President leaves?
Those edge cases defined the data model. The data model defined the product. Getting that wrong in design would have meant building something that looked right but broke the moment it hit real operational load.
I spent significant time before designing any screens just getting the recruiting team aligned on a shared stage vocabulary. Recruiter by recruiter. What does "screening" mean? What moves someone from "interested" to "qualified"? When is someone on the bench vs. out of consideration? That alignment work was unglamorous and it was the most important design work on the project. Every workflow downstream depended on it being consistent.
04The core design decision: purpose-built vs. adapted
Teamshares was already using Lever, a standard enterprise ATS. The obvious path was to configure Lever more intentionally and build tooling around it. I pushed back on that direction early.
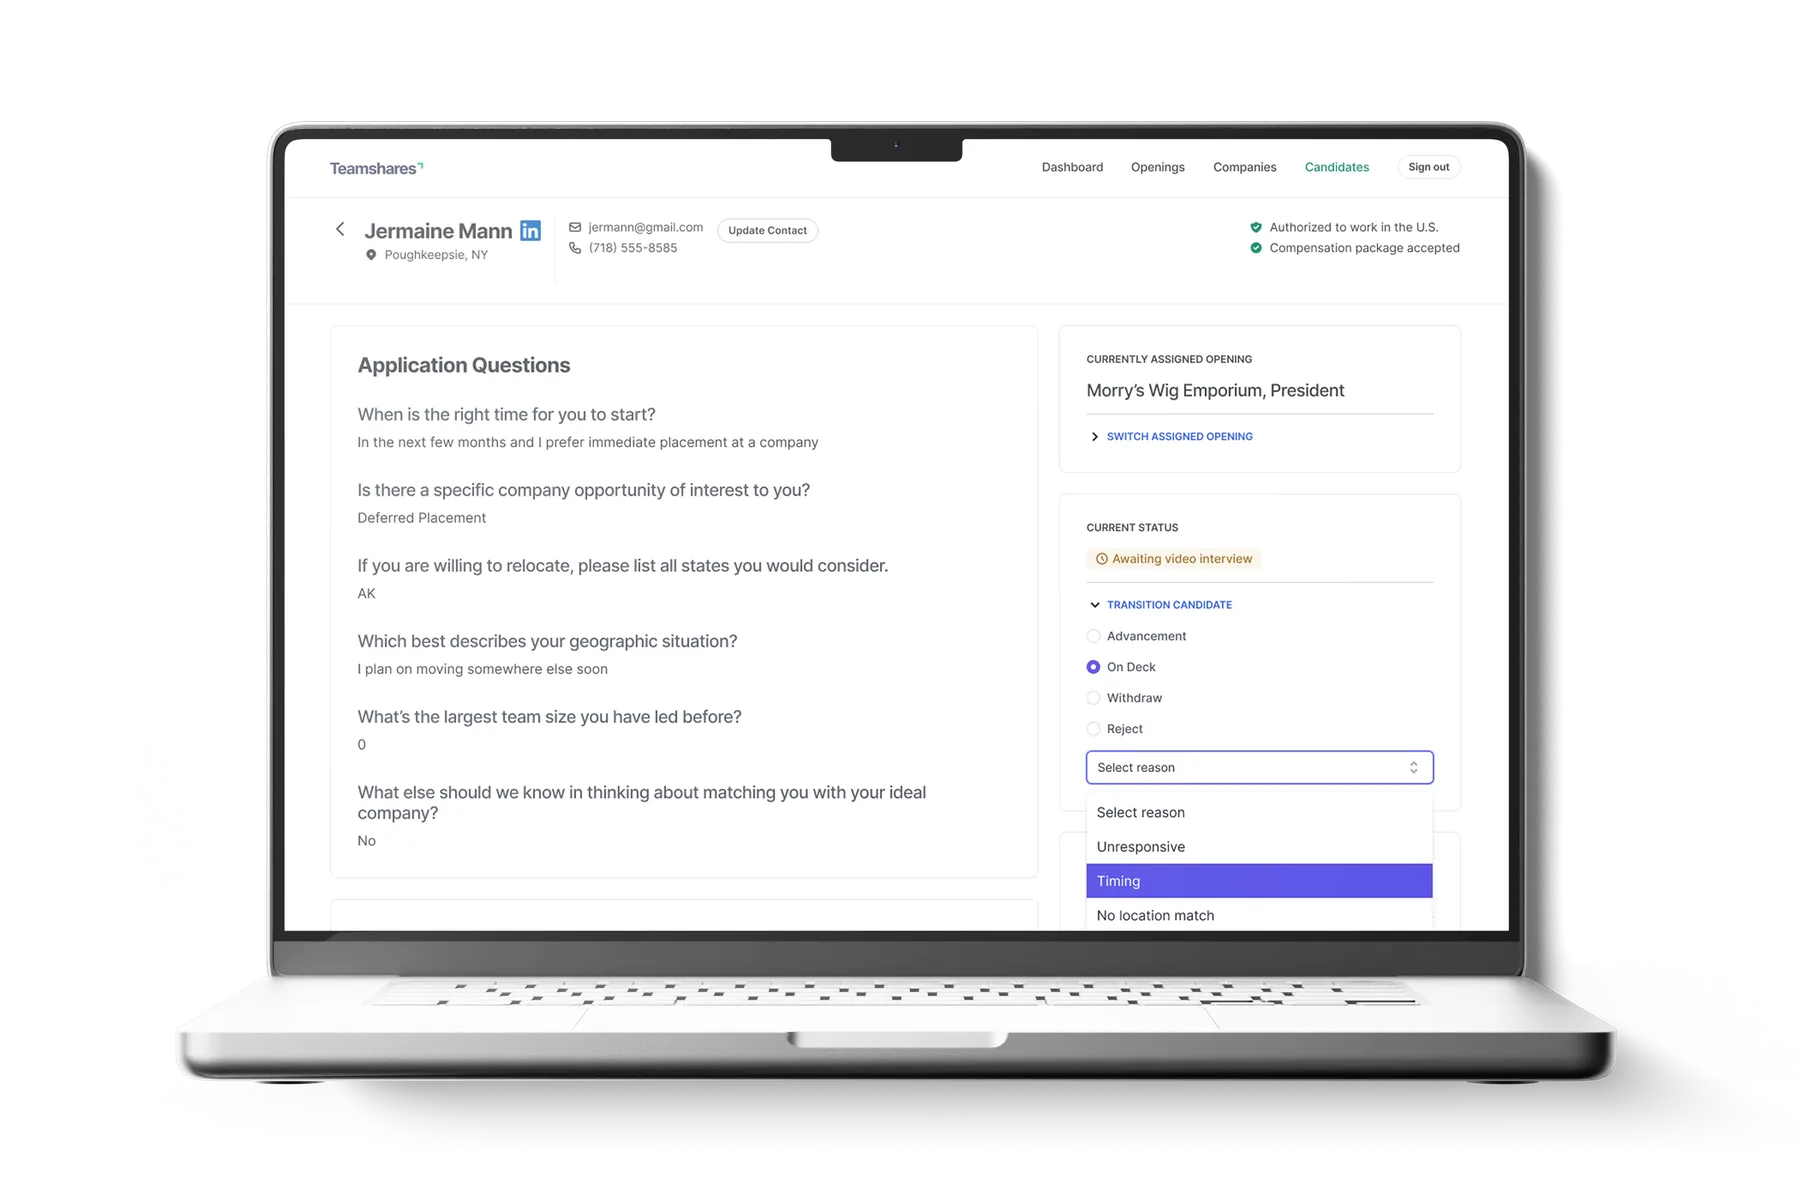
Lever's data model treated every candidate as moving toward a single job opening. Teamshares needed candidates to exist independently of any specific opening and be matchable to future placements. That's a fundamentally different architecture — beyond what any configuration of Lever could support.
05Shipping incrementally, learning under real load
The product shipped in sprints with the recruiting team using it in production throughout. That wasn't just a process choice — it was how I found the problems that don't show up in research.
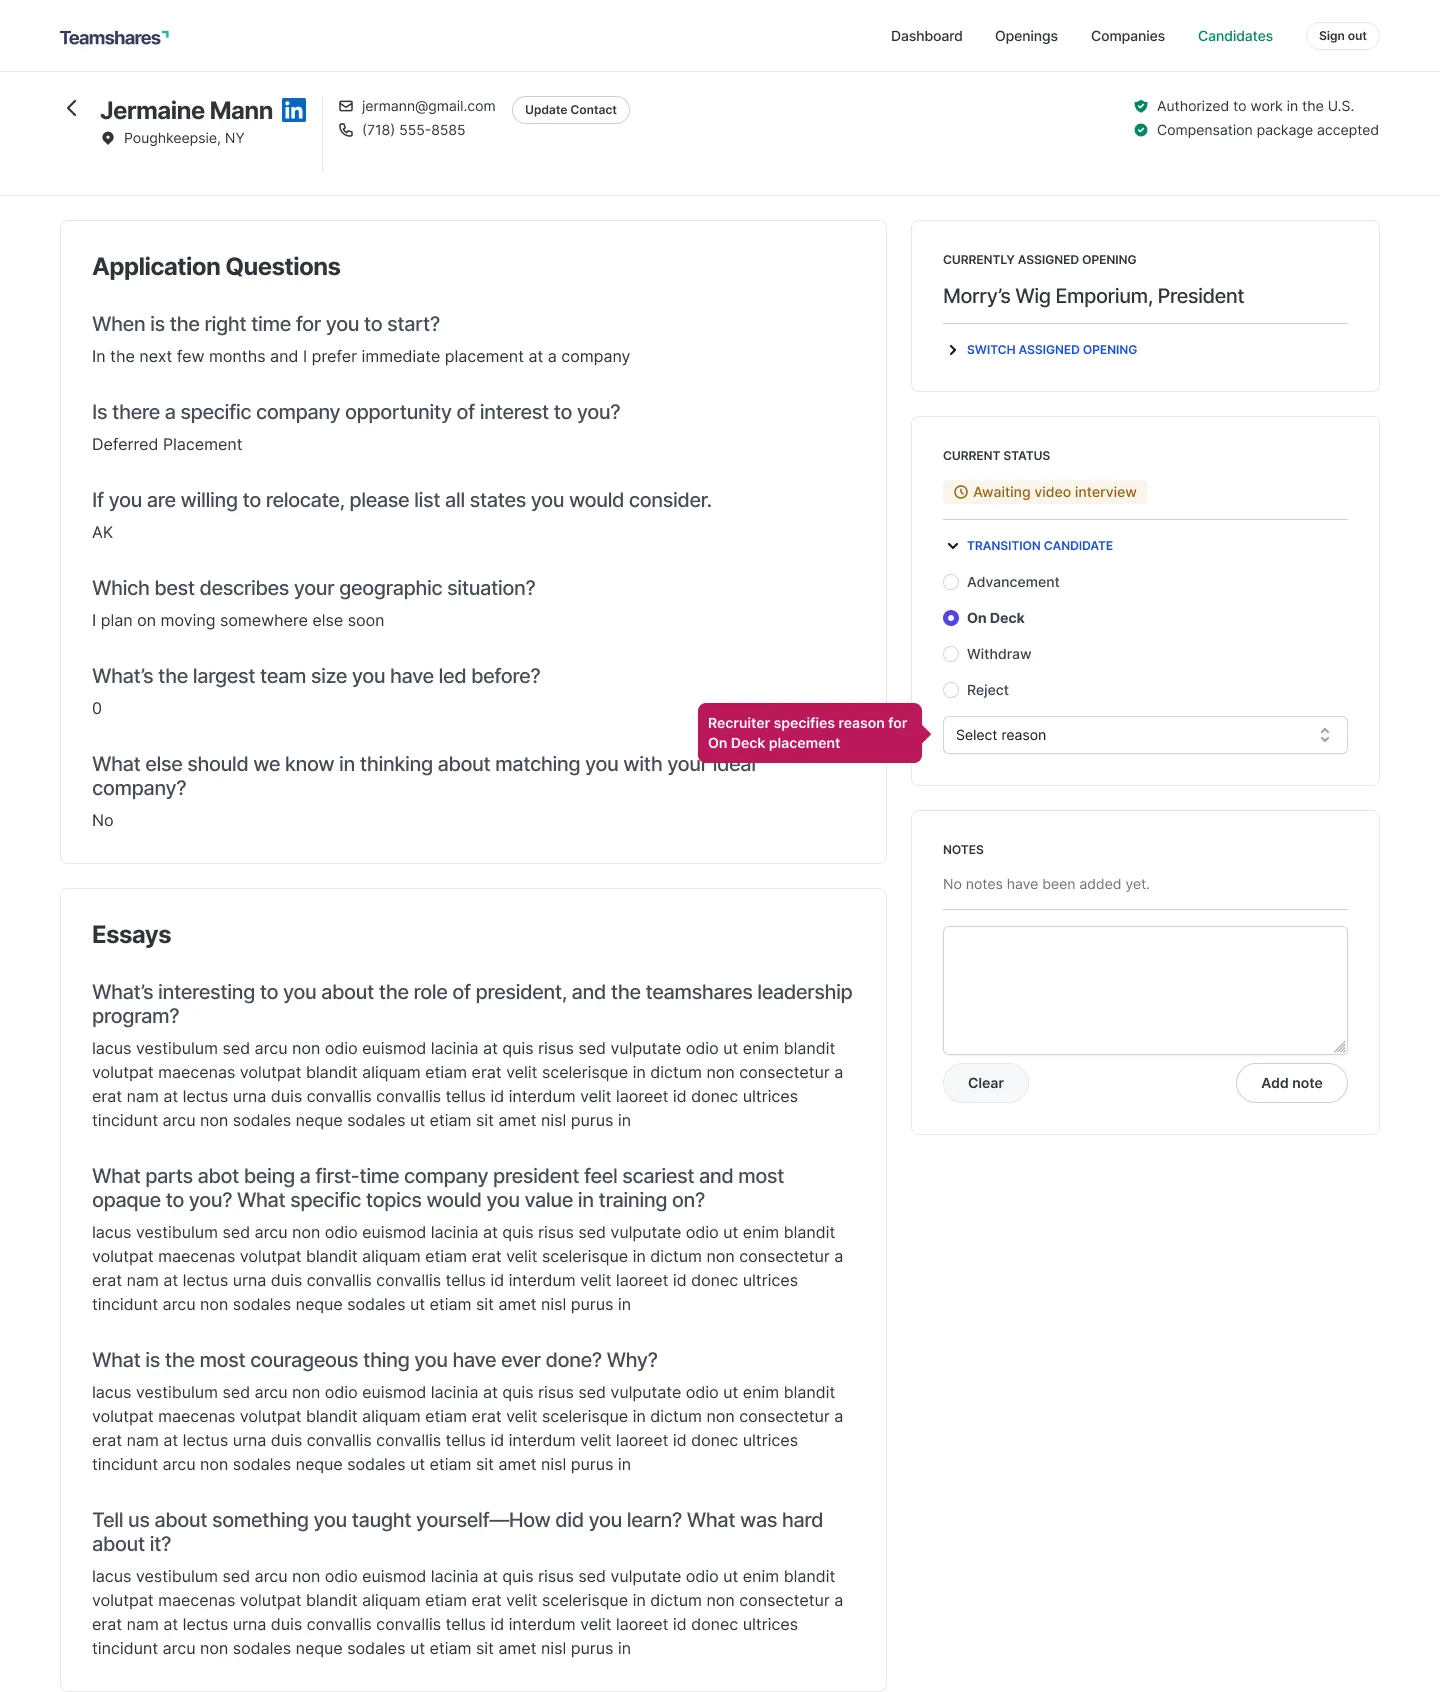 Candidate detail
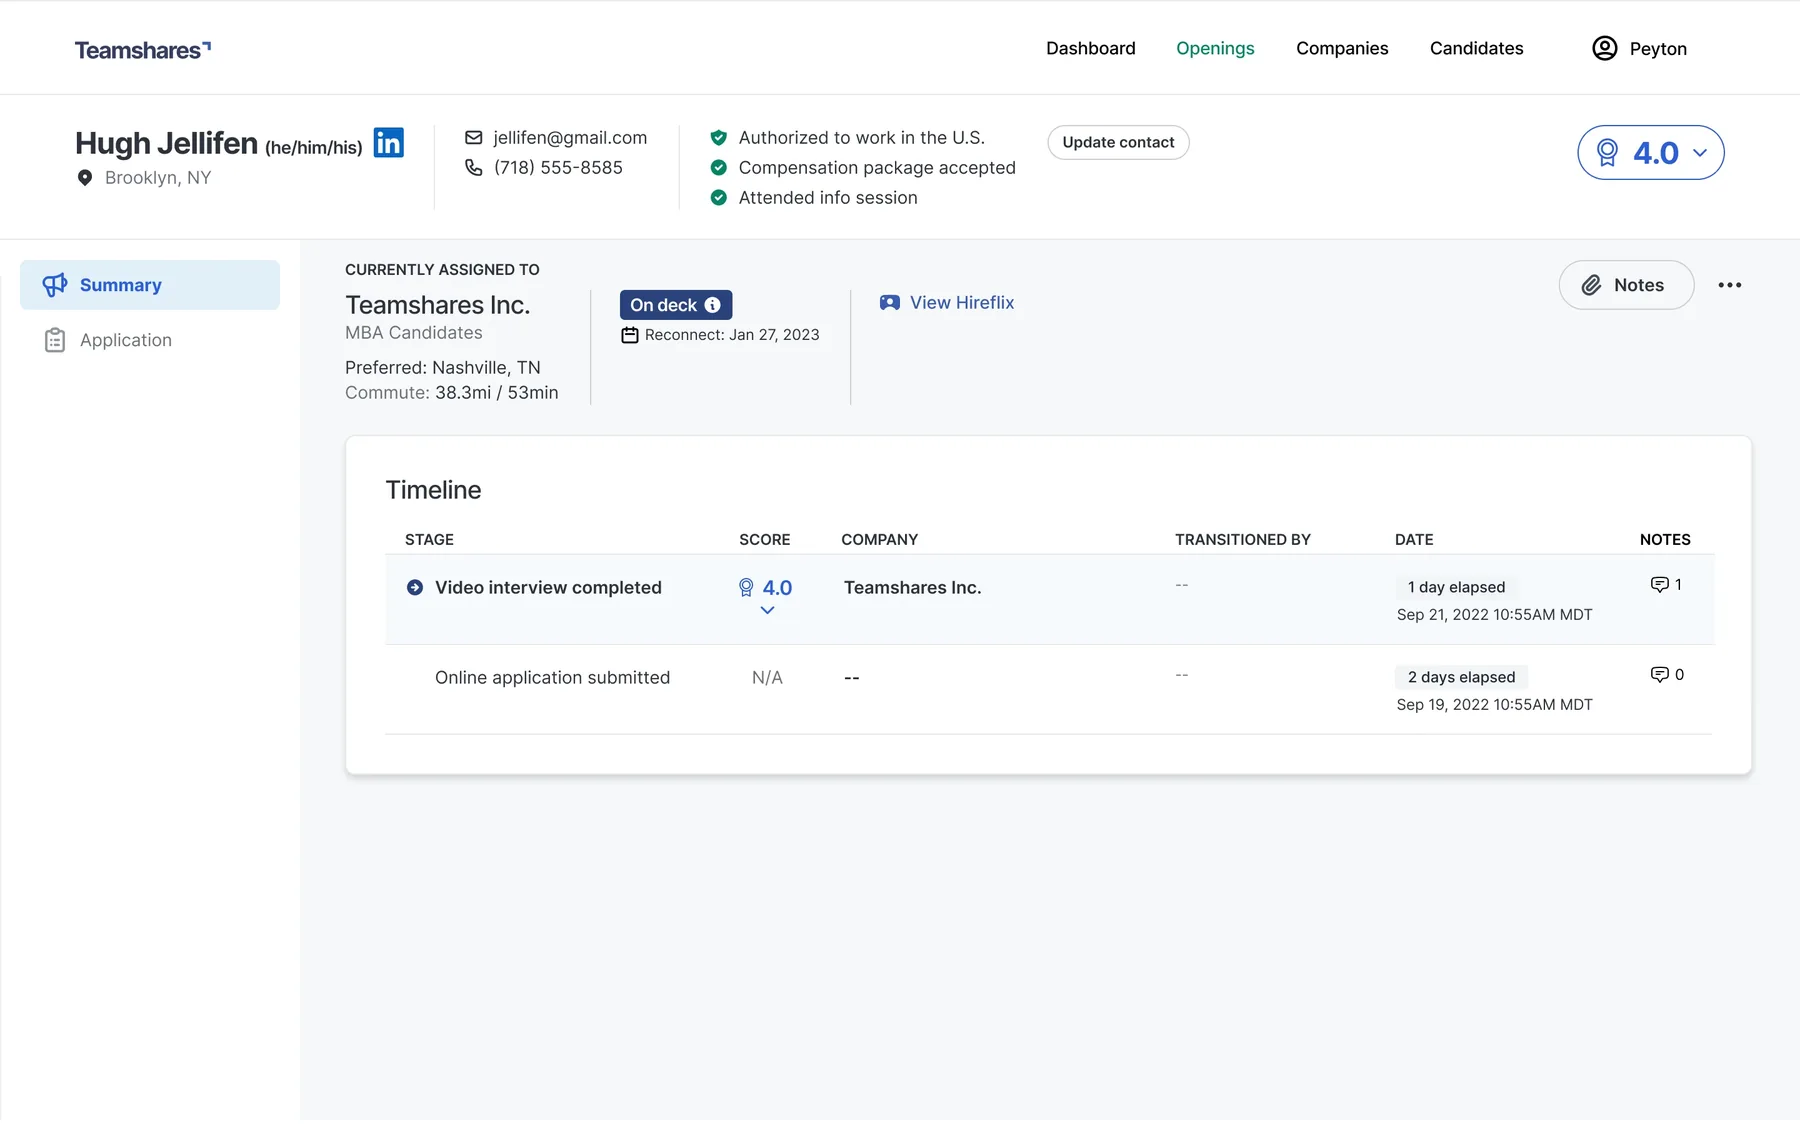 Scoring rubric
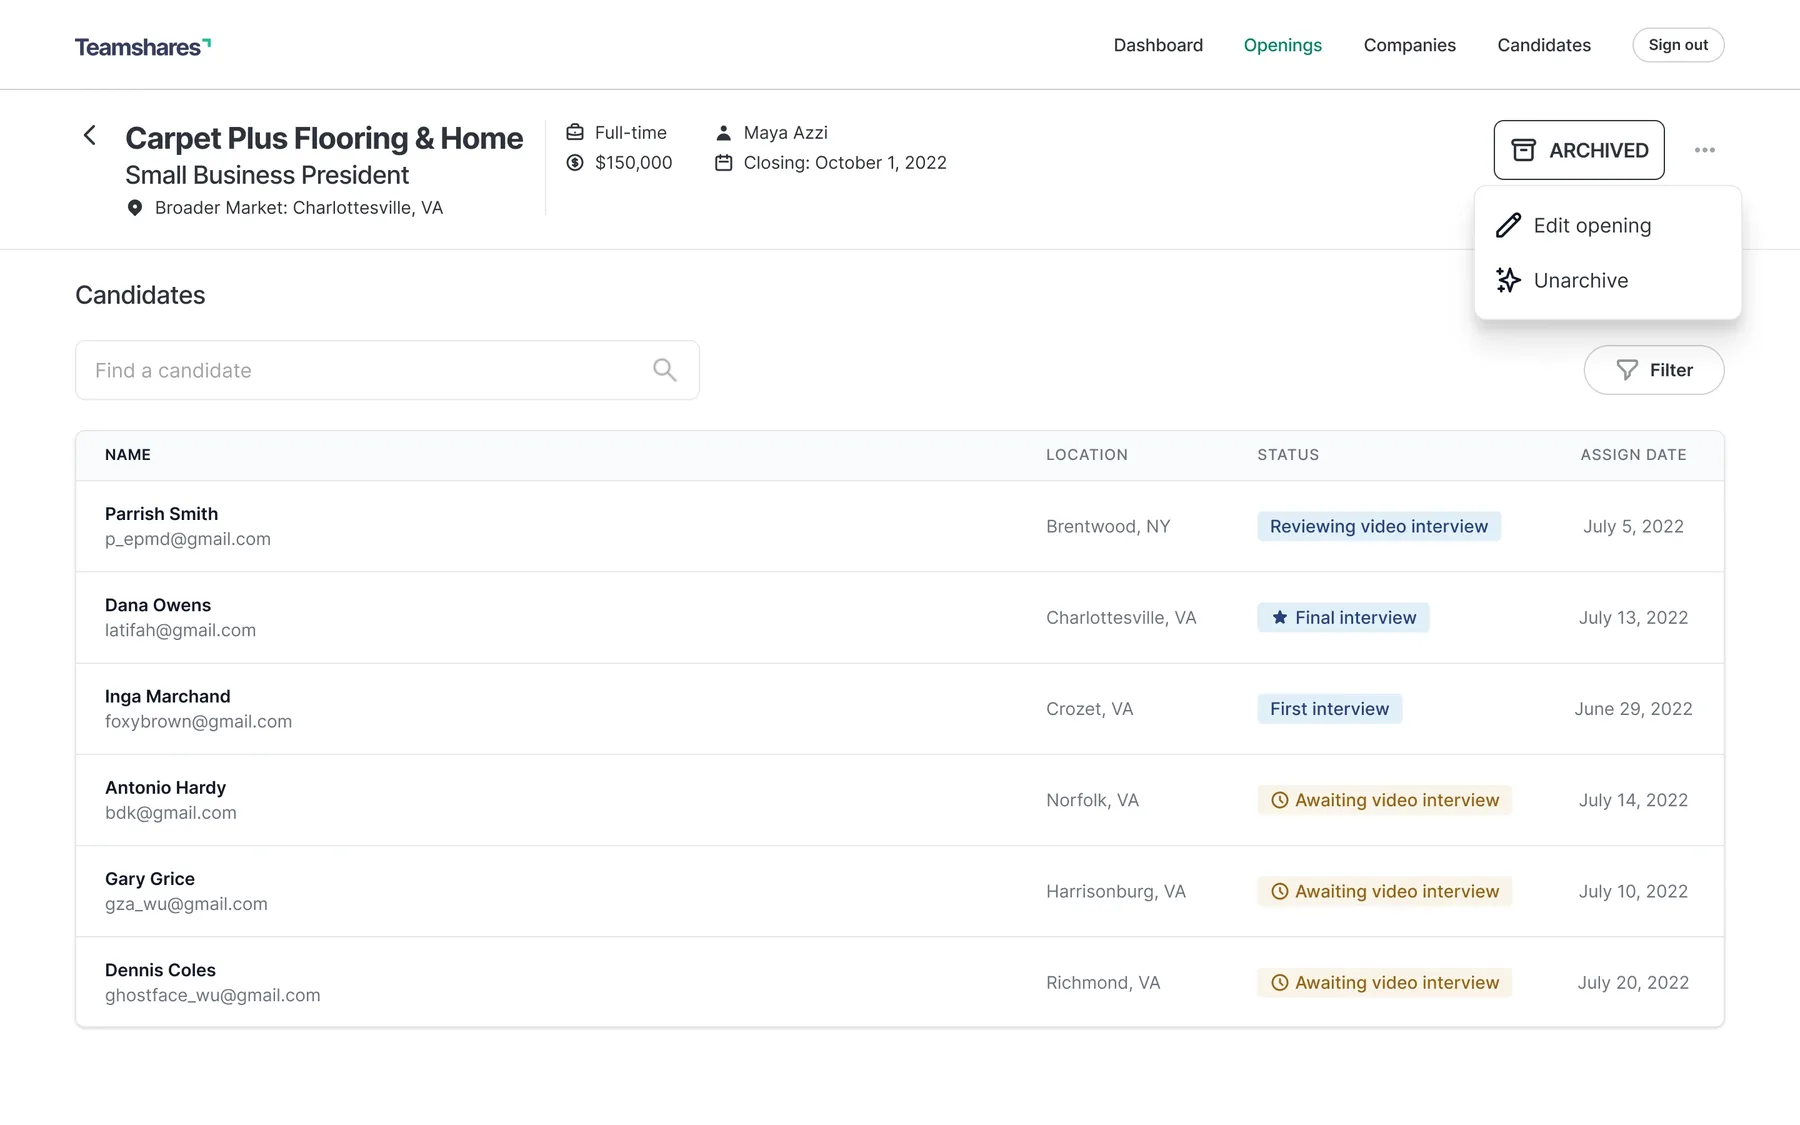 Bench & archiving
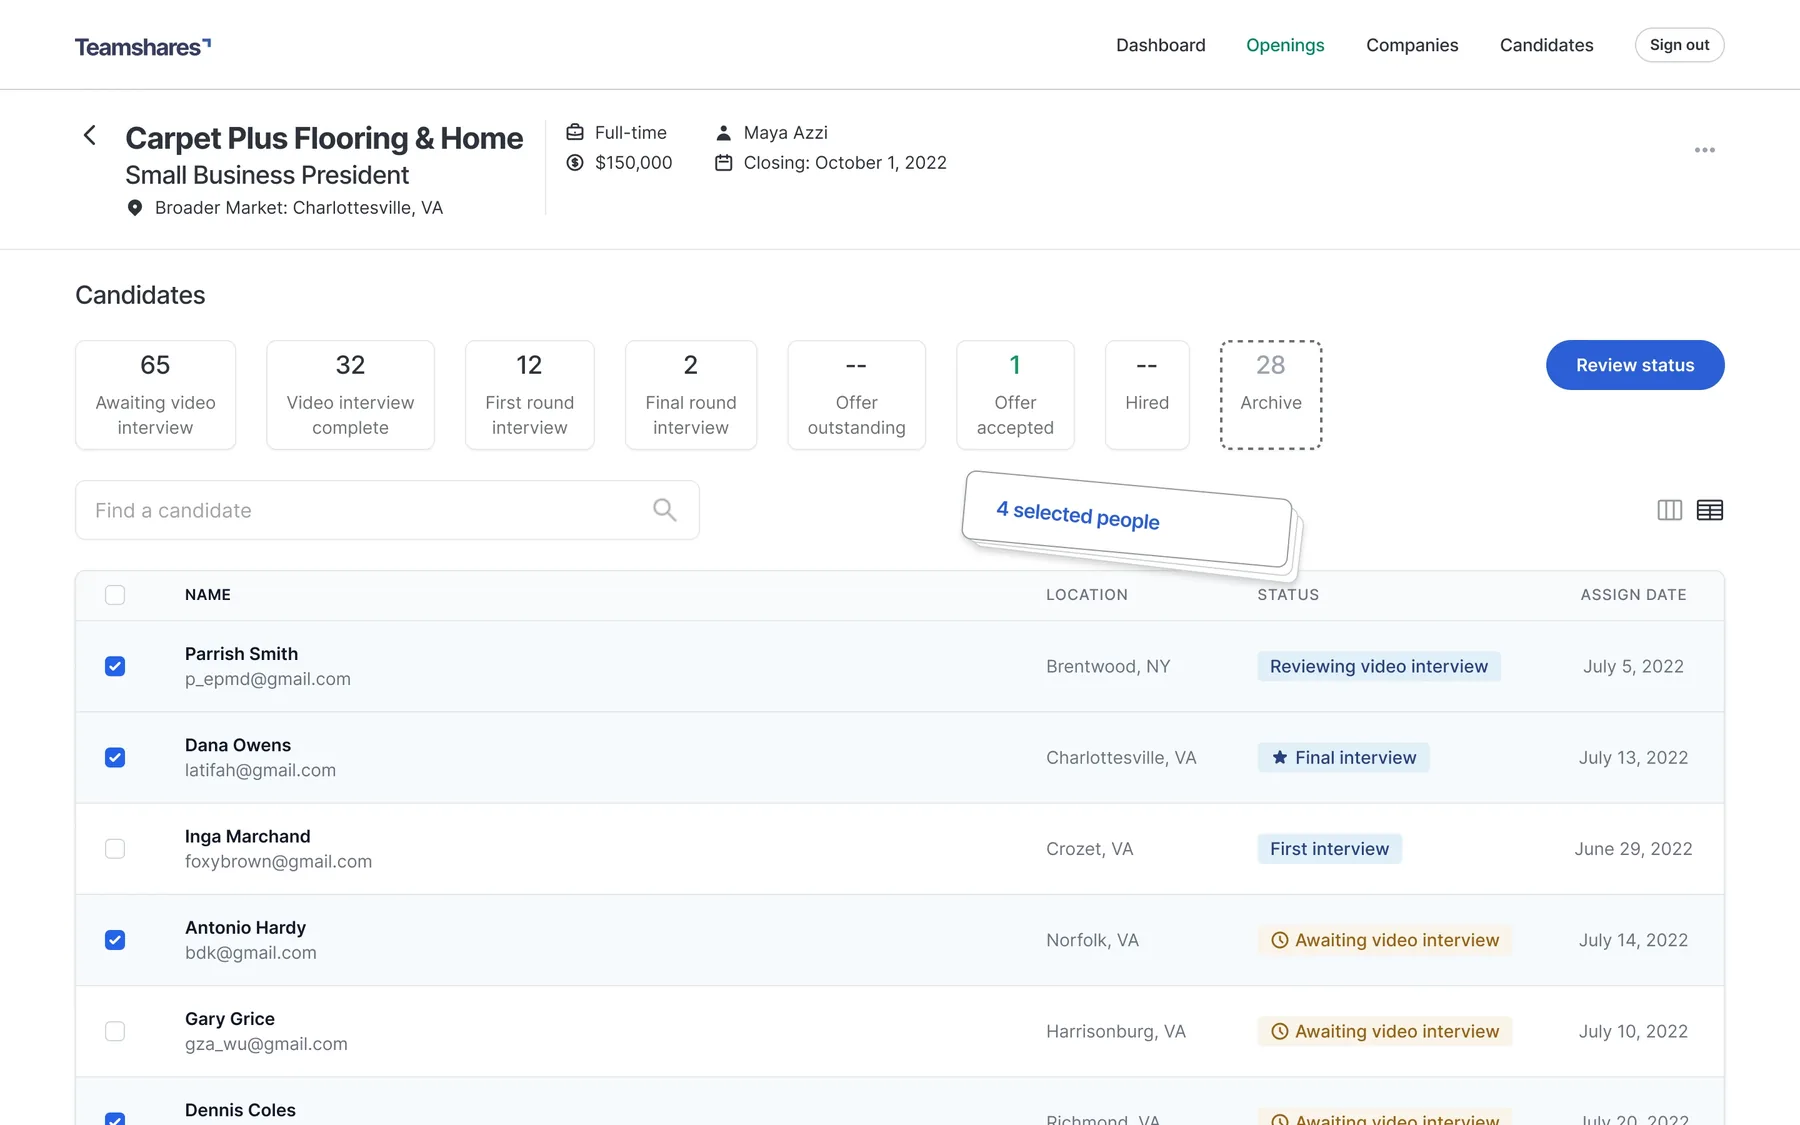 Bulk actions
"He's quick to step up and guide the team, especially in challenging situations."
Kevin Rikio Shiiba · Co-founder & CTO, Teamshares
06Candidate experience as a design constraint
Most internal tools treat the candidate as a data object. The kind of person Teamshares was recruiting — experienced operators, often leaving stable roles — had real leverage. They could walk.
Purpose-built candidate status messaging at each stage transition. Candidates knew what stage they were in, what came next, and roughly what the timeline looked like. This was a strategic retention mechanism for high-value candidates in a long process. Losing a finalist at week eight meant restarting a months-long process. The messaging investment paid for itself once.
07The future the data architecture was built for
Late in the project I started talking to Network Presidents — candidates who'd been through the process. What I heard shaped a direction nobody had formally proposed: a two-sided platform where candidates maintain profiles between application cycles, and Teamshares proactively matches upcoming openings to warm candidates already in the system.
The resourcing wasn't there to build it at the time, and the company reorganized before it could be pursued. But identifying and architecting toward a future state — even one that doesn't ship on your watch — is part of the job at principal level. You're not just designing for the current sprint. You're making decisions that either open or close future possibilities.
08What the outcomes actually measured
09What I'd do differently
The stage vocabulary alignment work was the right call, but I'd do it faster. I spent time working recruiter by recruiter to get buy-in on shared language when I could have run a structured workshop up front, documented the decisions, and moved on.
On the candidate experience: I'd push for it earlier. I raised it as a constraint mid-project, when it should have been in scope from the start. If I'd framed candidate retention as a business risk in the initial scoping conversation, it would have been in scope from day one.
Getting the right President into an acquired small business isn't an HR milestone. It's the unlock for employee ownership to actually work. Every hire placed through this system represented a business moving from a retiring owner's legacy into something owned by the people who run it. The spreadsheet couldn't hold that weight. The platform could. Designing systems that hold serious weight — and that don't break when the business scales past what anyone originally planned for — is the job.
Teamshares is a private company. Screens shown are representative of shipped work.
- 50+ components audited and standardized
- 100% adoption across product teams
- 2.5 yrs pre and post-acquisition runway
- 3 alumni now leading at LinkedIn, TikTok, AWS
01What was actually broken
Marketo was in the middle of a significant platform redesign. The component library existed, but it was maintained by a single person with no governance process and no real authority over what entered it. Patterns were diverging across the product. Teams were making local decisions that made sense for their surface and created inconsistency everywhere else.
The standard response to this situation is a design audit. Clean up the components, establish a style guide, ship an updated library. I didn't think that would work because it treated the symptom without touching the cause.
A design system maintained by one person with no governance will diverge. One person can't be everywhere. Without authority over what enters the system, every team becomes a de facto exception. The model that produced the components needed to change first. Fixing the model first was the only way to make sure the work didn't need to be redone in two years.
02Selling the structural fix before touching anything
Before any design work started, I got buy-in from my director and the VP of Product on a different model entirely. Not "we need better components." The pitch was: we need democratized ownership, embedded accountability, and governance that gives the design org actual authority over what enters the system.
That conversation happened before I had a single artifact to show. That was intentional. If you bring a governance proposal with a component library attached, people react to the components. If you bring the governance proposal alone, they react to the argument. The argument needed to land first.
The tradeoff with federated ownership: it's harder to manage. Contributors have other jobs. They're not full-time on the system, which means quality variance is a real risk. The governance layer was the answer to that — not as bureaucracy, but as a review process that gave contributors a clear bar and gave the central team real authority to hold it.
The thing I argued most directly: if you want 100% adoption, you need 100% of teams to feel like the system belongs to them. You can't mandate that. You have to architect it.
03Building the team deliberately
I was assigned two junior designers. I added a front-end tech lead and built a rotating PM model — product managers rotated in based on which component areas were in scope for their pods. That structure kept the work connected to real product needs instead of becoming a design-org-only exercise that shipped into a vacuum.
04Solving adoption before it was a problem
Most design systems fight for adoption after they ship. Teams have already built things their own way. Migrating is work. The system becomes a political negotiation instead of a shared resource.
I didn't want to have that fight. The federated model was partly a governance decision and partly an adoption strategy. When every team has a contributor with skin in the game, every team has a reason to use what comes out of it. The 100% adoption number was baked into the architecture from the start.
Embedded evangelists. Each product pod had someone who had contributed to the system and understood it from the inside. When new components shipped, that person was an advocate who could answer questions, explain decisions, and reduce the friction of adoption at the team level. You can't document your way to that. You have to build it into the org model.
05The audit and the new color system
Once the governance model was in place, the component work started. 50+ components audited, rationalized, and standardized. The audit surfaced the decisions that had never been made explicitly and were producing inconsistency across the product.
Color was the clearest example. The existing palette had grown by accretion. Colors got added when someone needed them, without a system behind the choices. The audit produced a new color system built around a coherent semantic model — not just a palette, but rules for how colors were used, when, and why. That made it defensible in review and teachable to contributors who weren't color-system specialists.
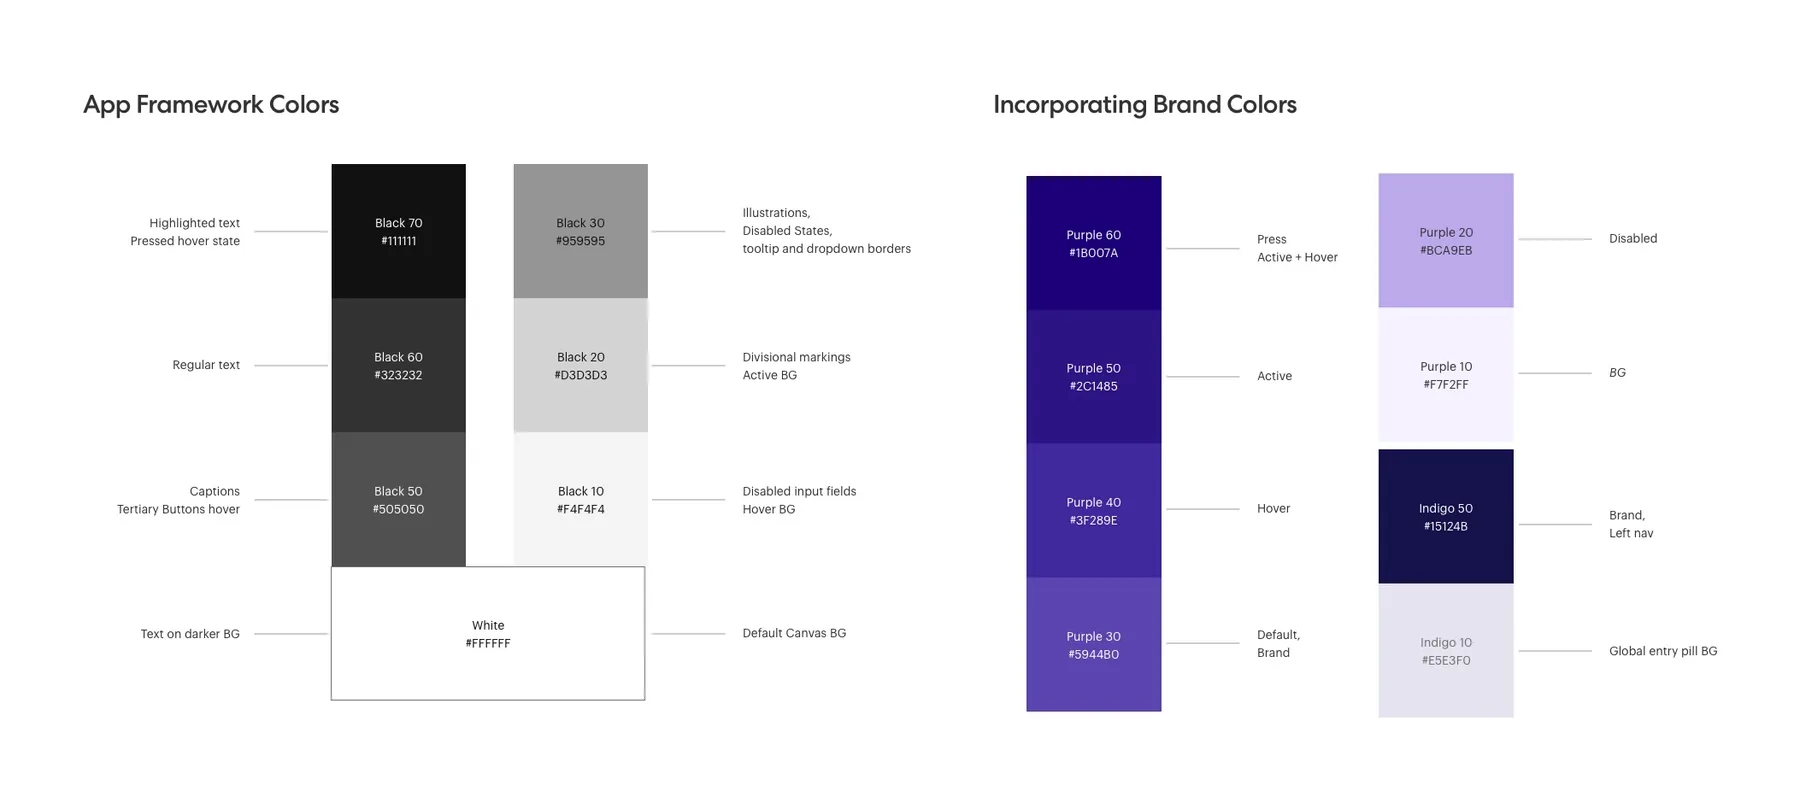
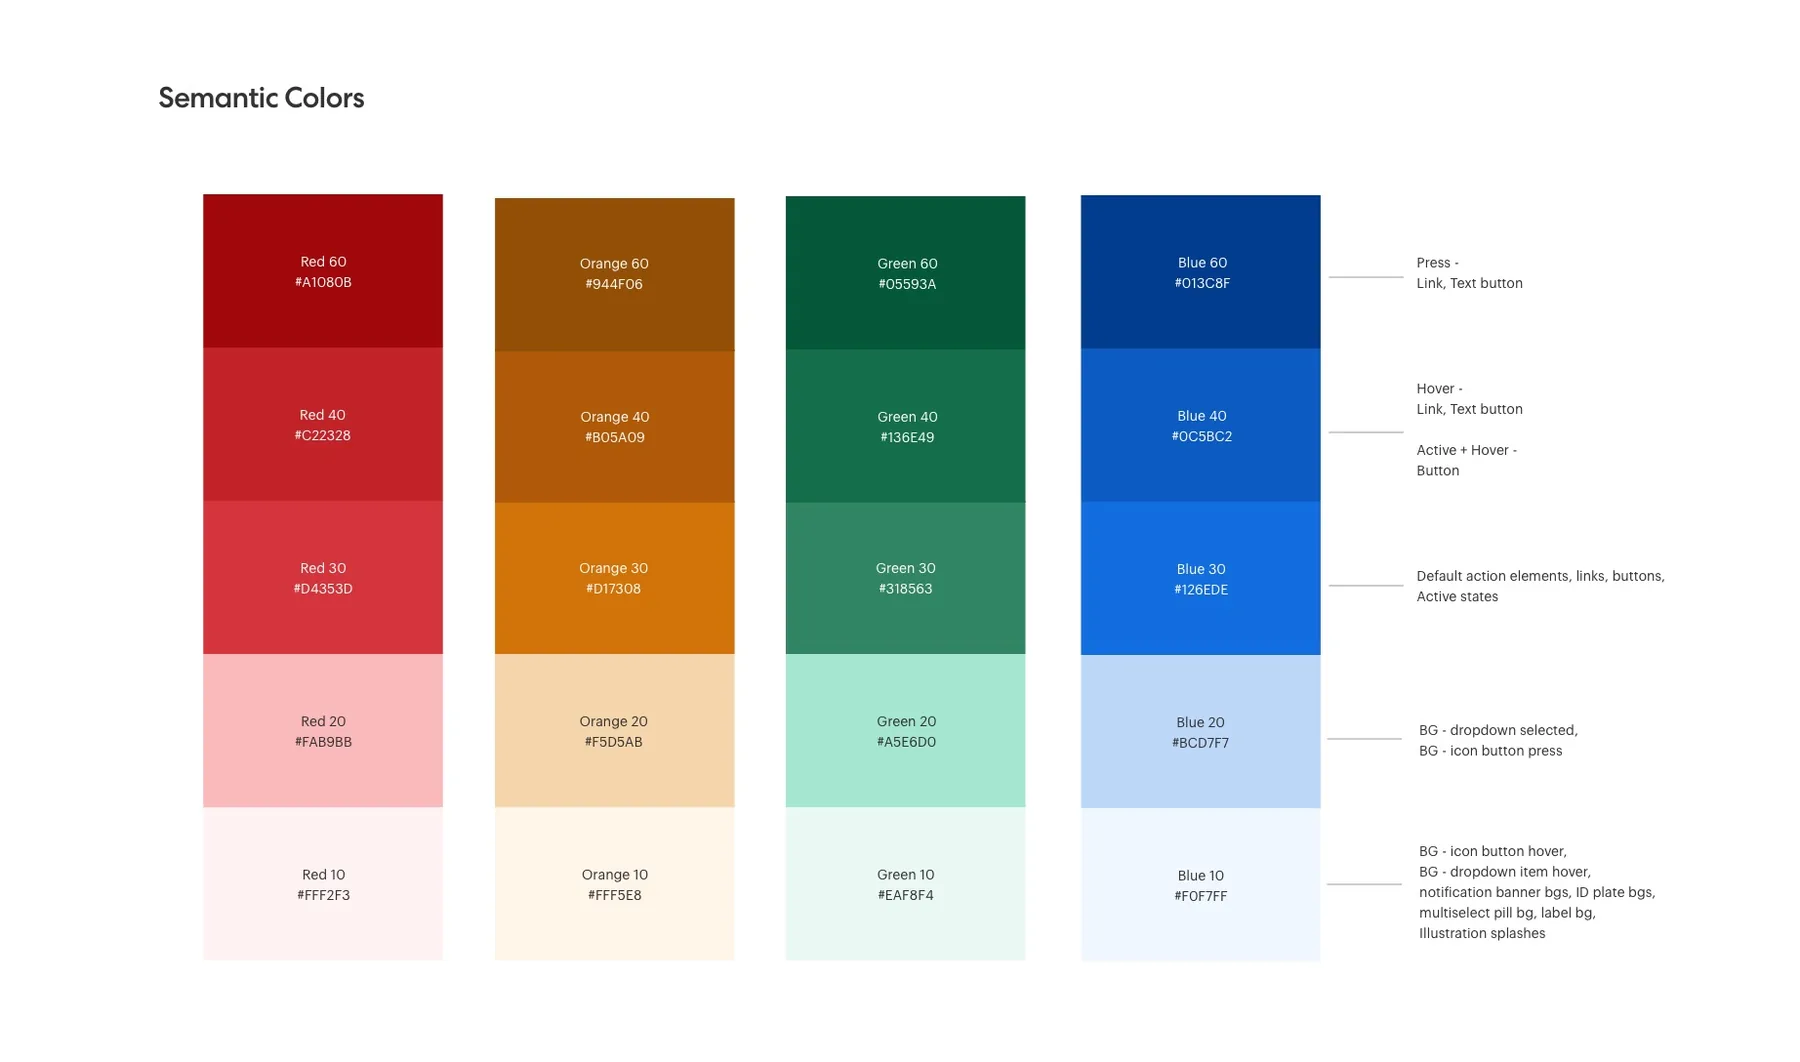
A color system tells you which color to use in which context and why. Without that layer, every new component becomes a judgment call, and judgment calls at scale produce drift. The semantic model gave contributors a framework to make consistent decisions without needing to escalate every choice to the central team. That's what made the governance scalable.
06Grounding in industry standards, which turned out to matter more than expected
In building Sky, we drew heavily from the leading design systems of the time: Predix, Polaris, Lightning, Spectrum. Not because there was any awareness that an acquisition was coming — there wasn't — but because building to industry-standard patterns was the right call for a platform at Marketo's scale. Enterprise B2B software has established conventions for a reason. Working against them costs you in onboarding, in accessibility, and in credibility with technical stakeholders.
That decision turned out to be a significant factor when Adobe acquired Marketo. The migration to Adobe's design language was less disruptive than it could have been precisely because Sky was already built on patterns that Adobe's Spectrum system recognized. That's a case where doing the right thing for the wrong-sounding reason — "just because it's good practice" — turned out to have real strategic value after the fact.
07The acquisition: Sky's patterns going upstream into Spectrum
Adobe acquired Marketo. The expectation would be that the acquired company's design system gets absorbed into the acquirer's. That's mostly what happened. But not entirely.
Several Sky patterns — data visualization approaches, card treatments — found their way upstream into Spectrum, Adobe's own design language. An acquired company leaving fingerprints on the acquirer's system. That's not a common outcome, and it happened because Sky was built to a standard that Adobe's design org could recognize and evaluate on its merits, not dismiss as a legacy artifact from an acquired product.
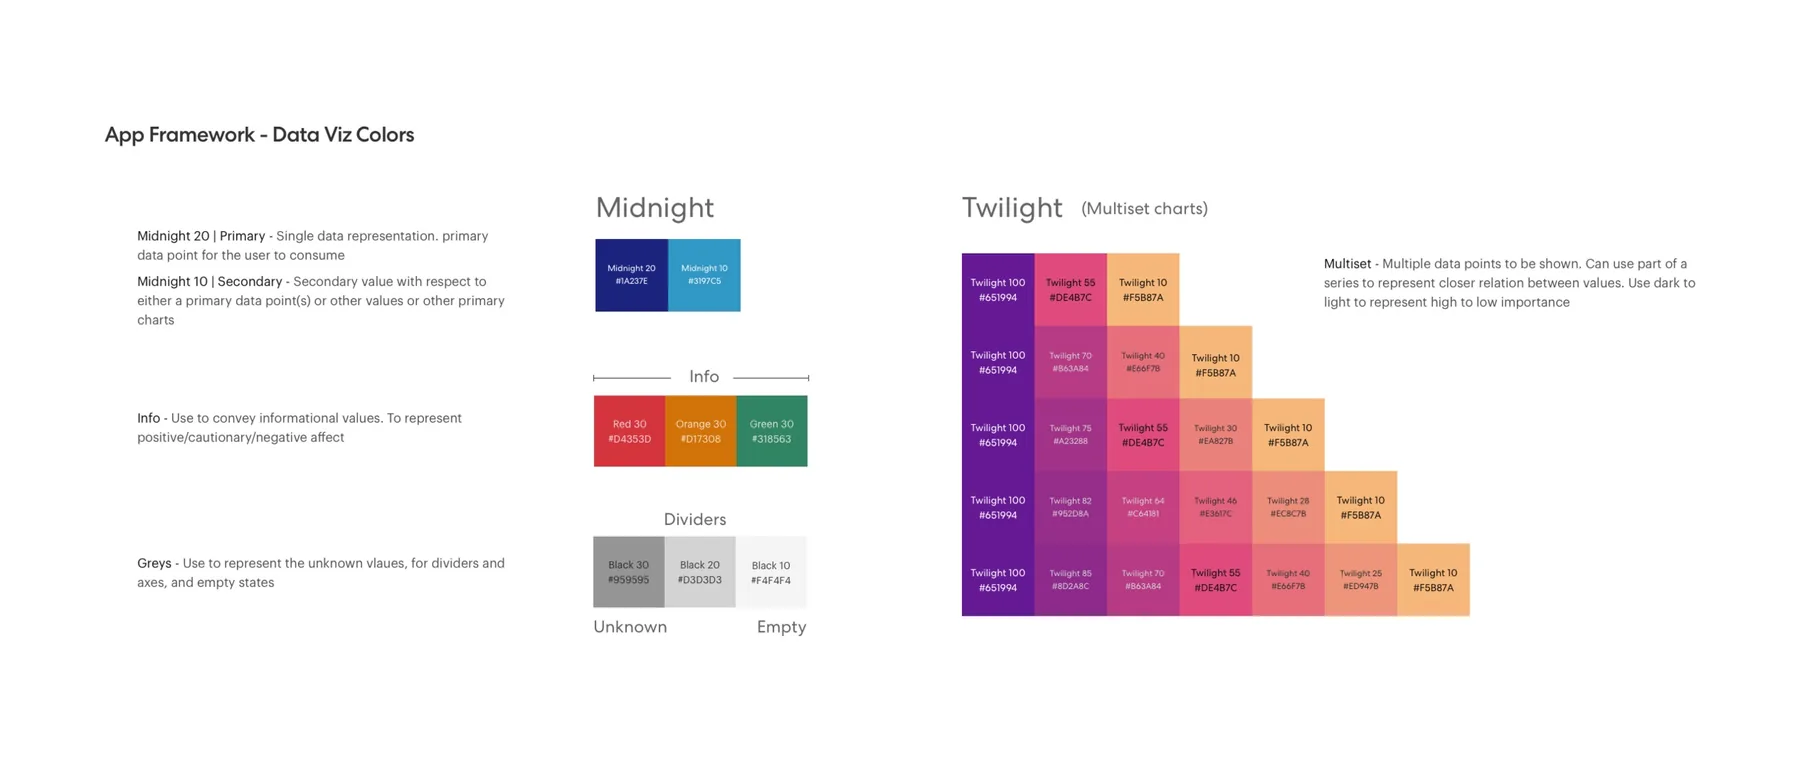
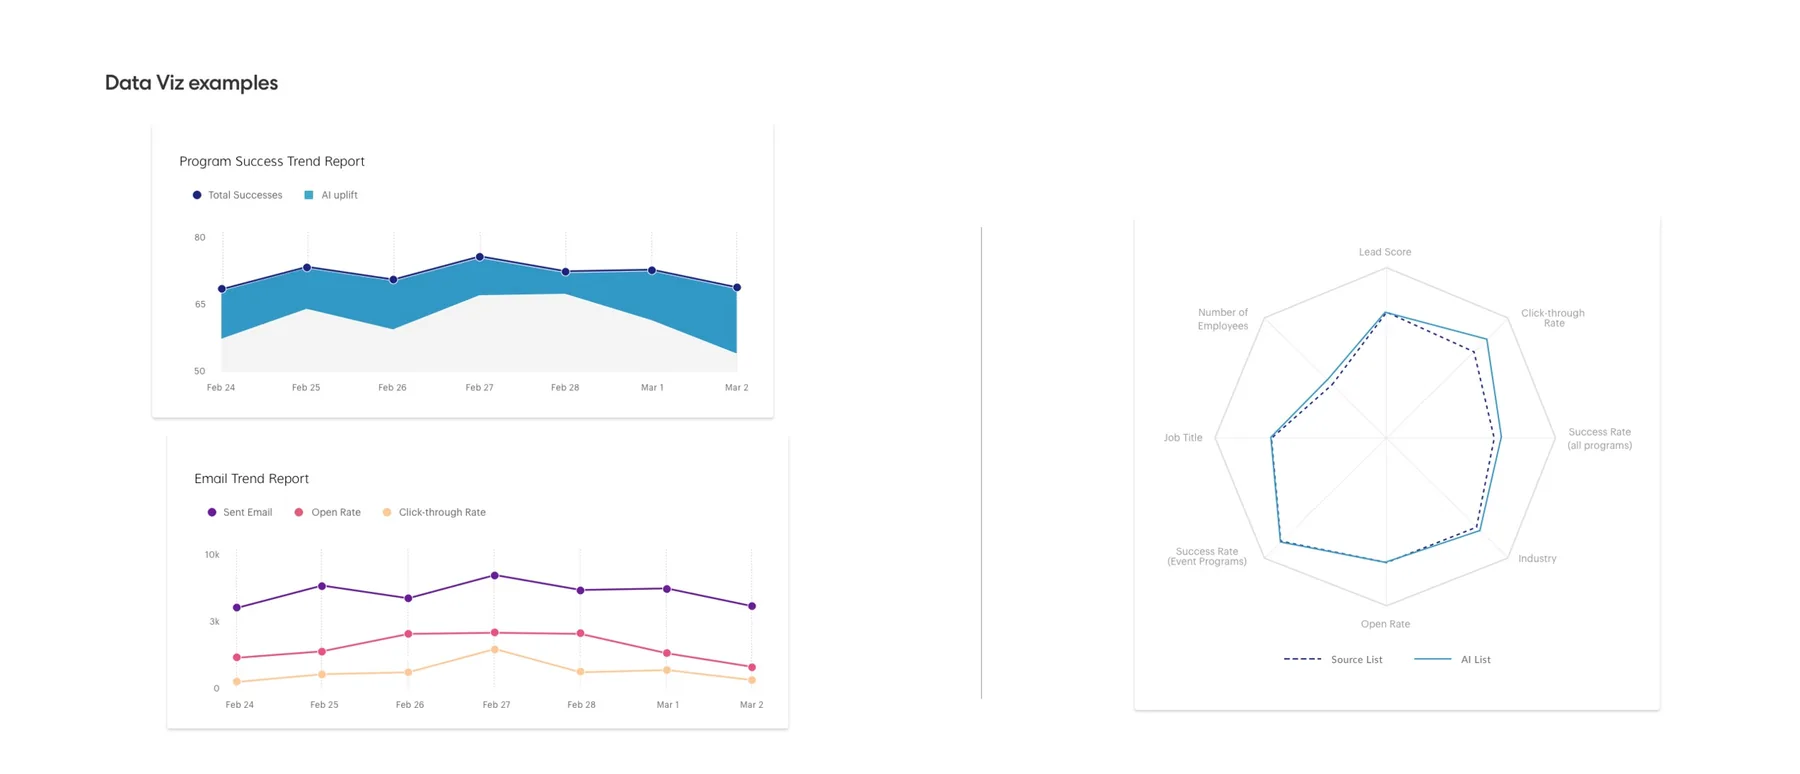
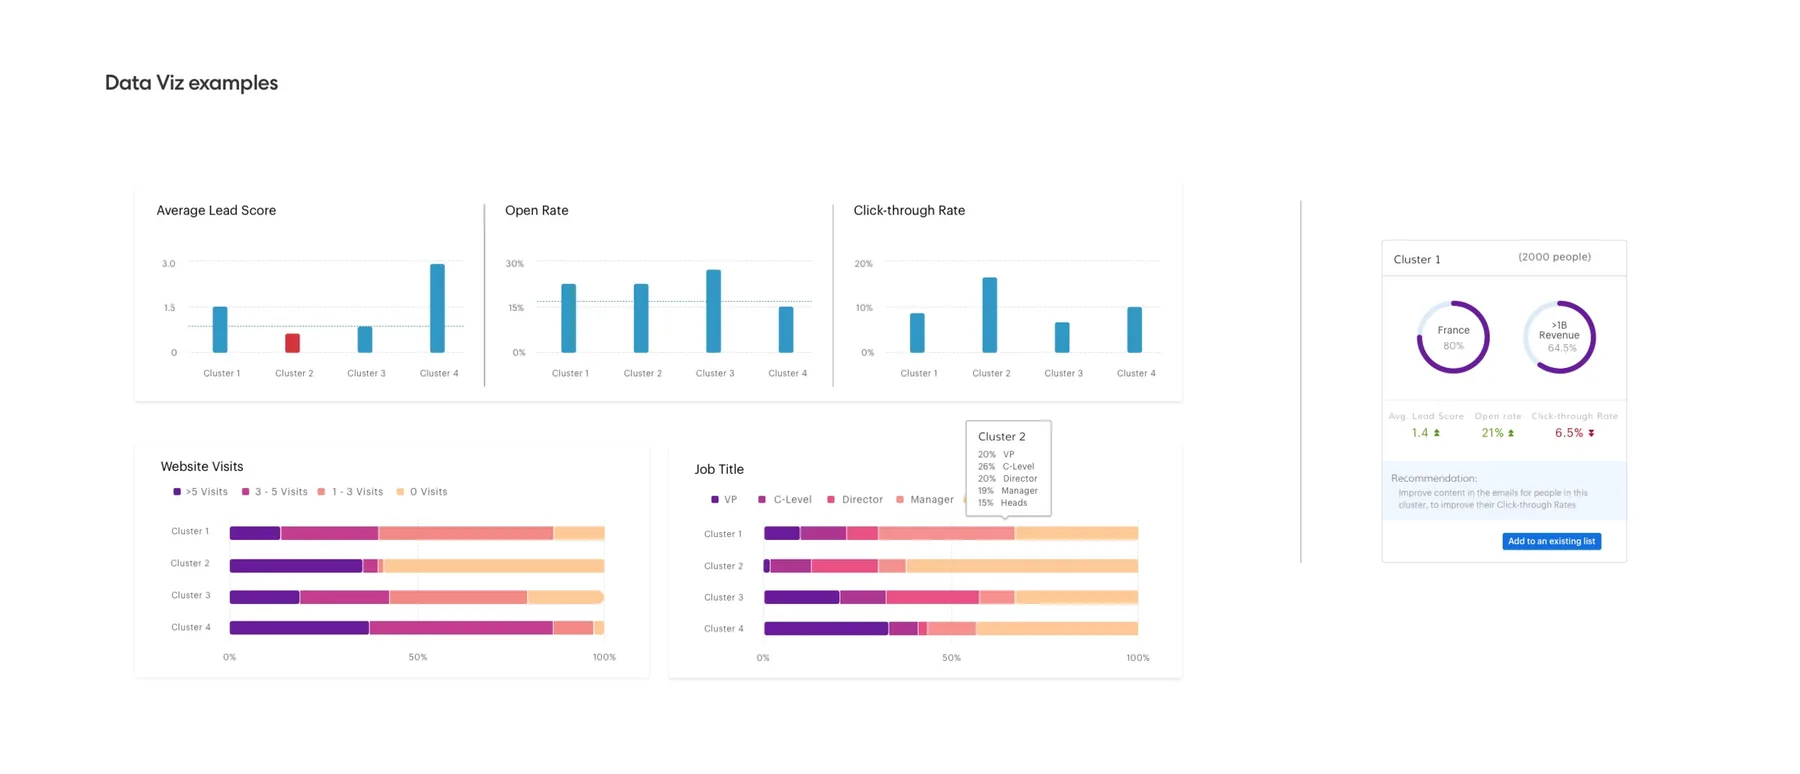
The upstream contribution is evidence that the system was built with enough rigor that one of the largest design organizations in tech looked at it and said: this is better than what we have in this area. That happens with a system that has a real point of view, documented decisions, and patterns that generalize beyond the product they were built for.
08What the team became
The designers I developed through this work went on to lead design systems and design functions at some of the most design-mature organizations in the industry. That's not incidental to the project — it's a result of it. Working on a real system, with real governance, real contributors, and real stakes is a different kind of development than working on a product feature.
I take that seriously as a measure of the work. A design system that produced three alumni at that level means the people who worked on it learned something real. That's only possible if the work itself had depth — if there were hard decisions to make, real tradeoffs to navigate, and a governance model that required people to think in systems rather than in screens.
09What the numbers actually mean
10What I'd do differently
The governance model worked, but it took longer to fully operationalize than it should have. The federated ownership concept was sound. The documentation of what that meant in practice — how contributions got reviewed, what the bar was, who had final authority on edge cases — lagged behind the system itself. That created ambiguity in the early months that I had to resolve one conversation at a time instead of by pointing to a process.
I'd write the governance playbook first, before the first contributor joined. Not a long document — a one-pager that answered the three questions every contributor needed: what's my responsibility, how does my work get reviewed, and who has final say. That clarity would have shortened the ramp-up time considerably.
On the upstream Spectrum contribution: I'd document the pattern decisions more rigorously in real time. Some of what we contributed worked its way into Spectrum through conversations and informal knowledge transfer rather than clean handoffs. The patterns landed, but the reasoning behind them was harder to transfer than it would have been if we'd been writing decision records as we made the decisions. That discipline would have made the contribution more durable.
A design system is a bet on how a team will make decisions over time. The components are almost beside the point. What matters is whether the governance model produces consistent decisions at scale without requiring a central authority to weigh in on everything. Sky worked because the model worked — and the model worked because it was designed before the components were. That sequencing is the lesson. Get the org right, then build the thing.
- 10x addressable market expansion
- 4x improvement in user engagement
- 33% reduction in time to resource creation
- 3 enterprise contracts tied directly to the pivot
01What was actually going on
Meroxa had a working product. Visual pipeline builder: connect a source, connect a destination, watch data flow. Clean concept, demos well, early traction. Then the growth curve went flat.
The instinct in the room was that something was wrong with the experience. Better onboarding. Cleaner UI. Smoother first run. I had a different read after the first few research sessions: we weren't talking to the person we thought we were building for, and that wasn't a UX problem.
We'd built the product for Data Engineers. The people actually using it and bumping against its limits were Software Engineers on production teams. Those aren't the same role. They have different mental models, different tooling expectations, and completely different anxieties. We'd accidentally found a different market. The question was whether we had the nerve to acknowledge it and go there on purpose.
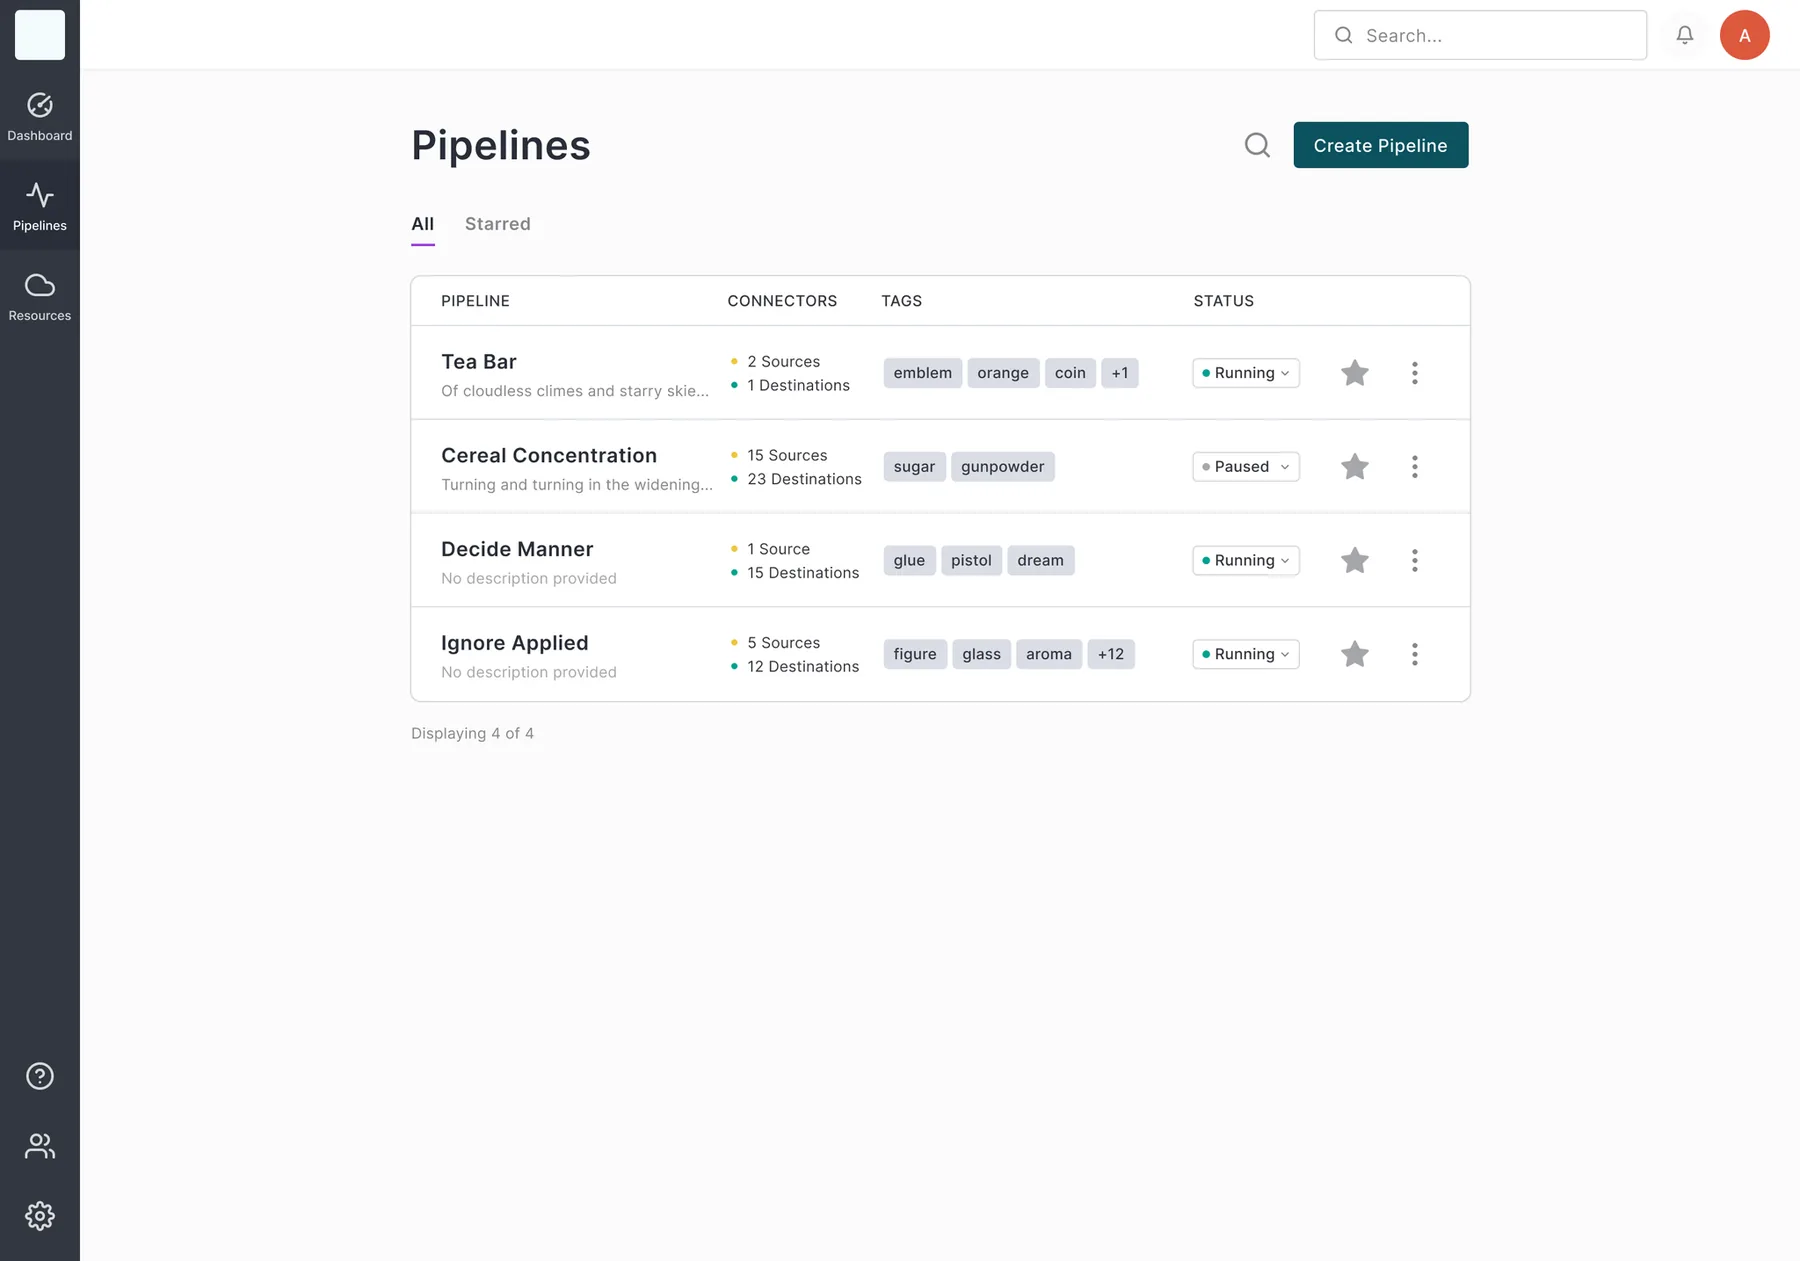 Pipeline builder — the original product
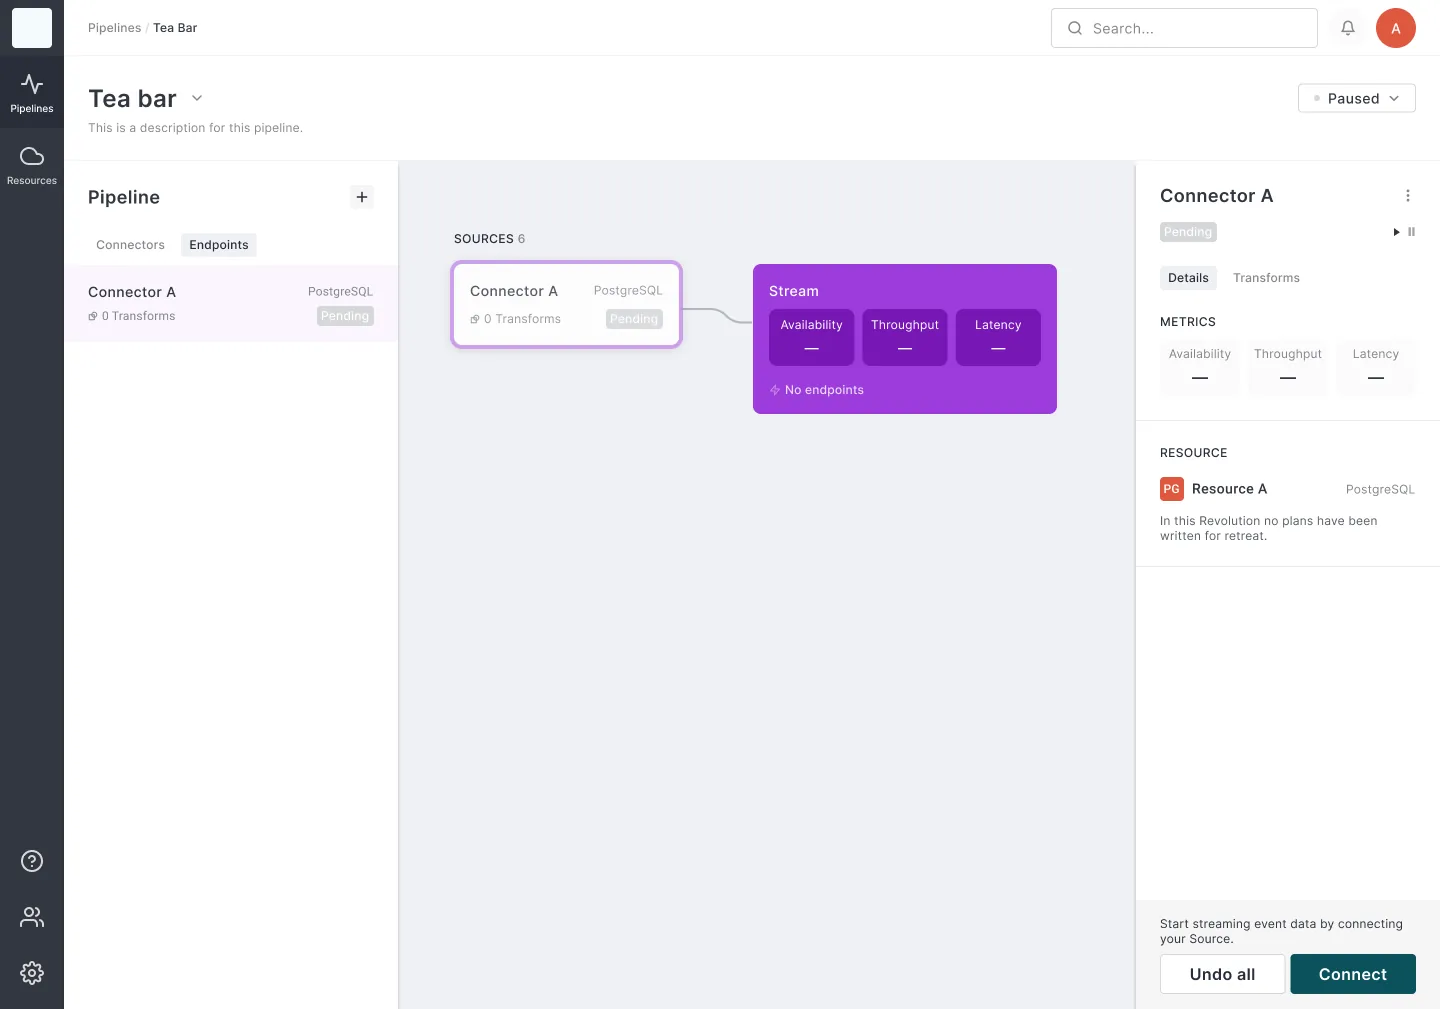 Connector view
02How I ran the research
The VP of Product had started picking up on this in customer calls. I took ownership of making it rigorous: 14 sessions across active users, churned users, and prospects we re-recruited specifically to stress-test the persona assumption. I wasn't looking for feature requests. I was looking for three things.
Who is actually reaching for this product and why — not what they say in intake surveys, but what prompted them to show up. What workarounds they'd built that the product couldn't support. And what a bad Tuesday looks like for them operationally, because that's where the real job-to-be-done lives.
03Taking it to leadership
Research findings are only worth something if they move decisions. The VP of Product and I didn't bring this to exec leadership as a design presentation. We brought it as a business case.
The framing was deliberate. Don't lead with "our users aren't who we thought." Lead with "here's the market we're currently walking past." Production engineering teams are a 10x larger addressable market than the Data Engineer segment we'd been targeting. We'd accidentally landed in that market with a product that couldn't serve it. A focused pivot toward a code-first developer experience, real-time observability, and multi-environment support would turn a lucky accident into a real position.
Leadership was already worried about growth. The hard part wasn't convincing them something was wrong. It was giving them a path forward that felt like opportunity rather than retreat. "There's a 10x market one pivot away" reframes the same facts into an opportunity. That reframe was intentional, and it's what got us a yes.
04The call that unlocked everything else: code-first vs. visual
The original product was built around drag-and-drop. The new audience didn't want that. Software Engineers are skeptical of tools that abstract away what's actually happening. They want to write code, version control their infrastructure, and know exactly what's running where. The first big design decision was whether to evolve the visual paradigm for the new user or walk away from it entirely.
We ran two weeks of concept testing. The answer wasn't close.
Option A felt safer. It preserved more of what we'd built. But engineers in testing kept asking the same question: "which one is the source of truth?" A hybrid that doesn't fully commit to either mental model serves nobody well. The visual builder wasn't wrong — it was solving the wrong problem. Keeping it on life support would have diluted both experiences.
05Rethinking the IA from scratch
The original IA was pipeline-centric. Pipelines were the top-level object and everything nested under them. That made sense when the UI was the construction tool. It made no sense when the UI was the observability layer.
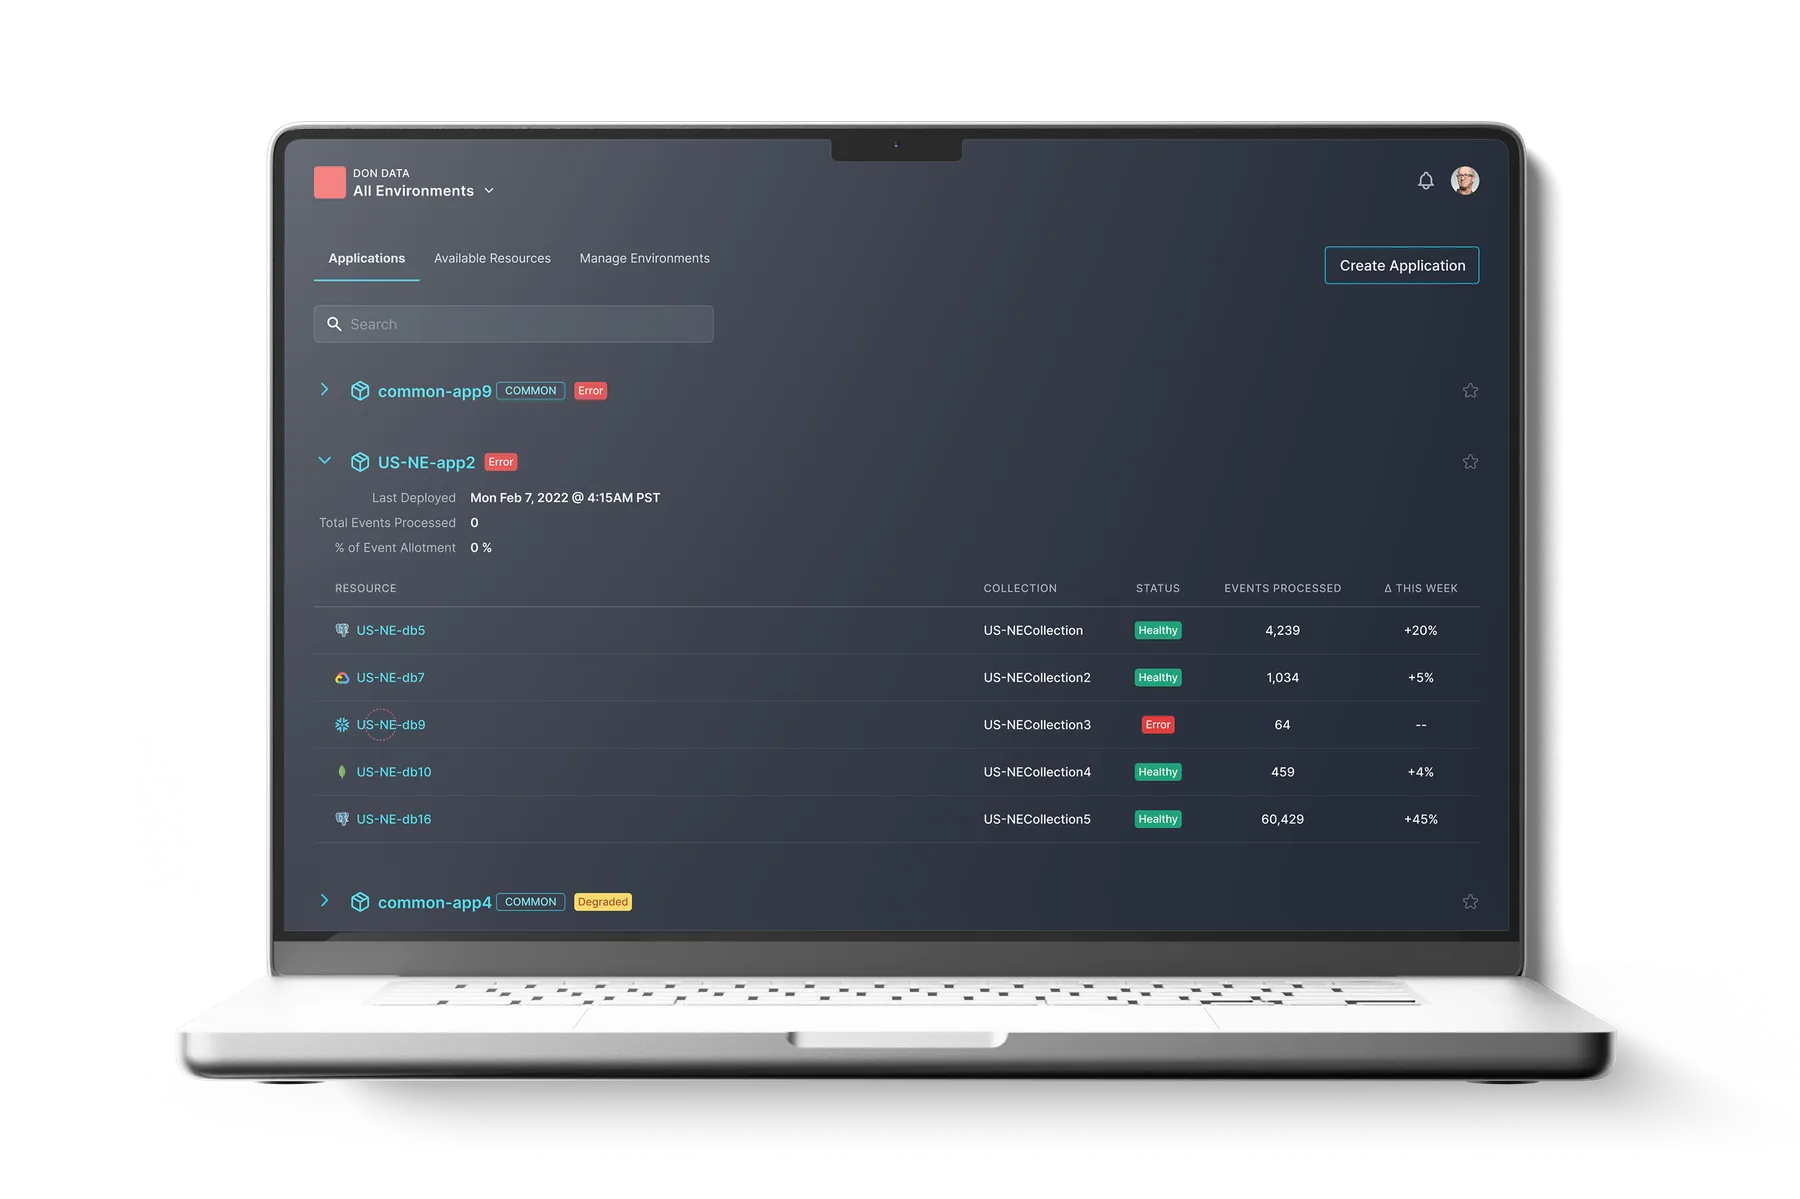
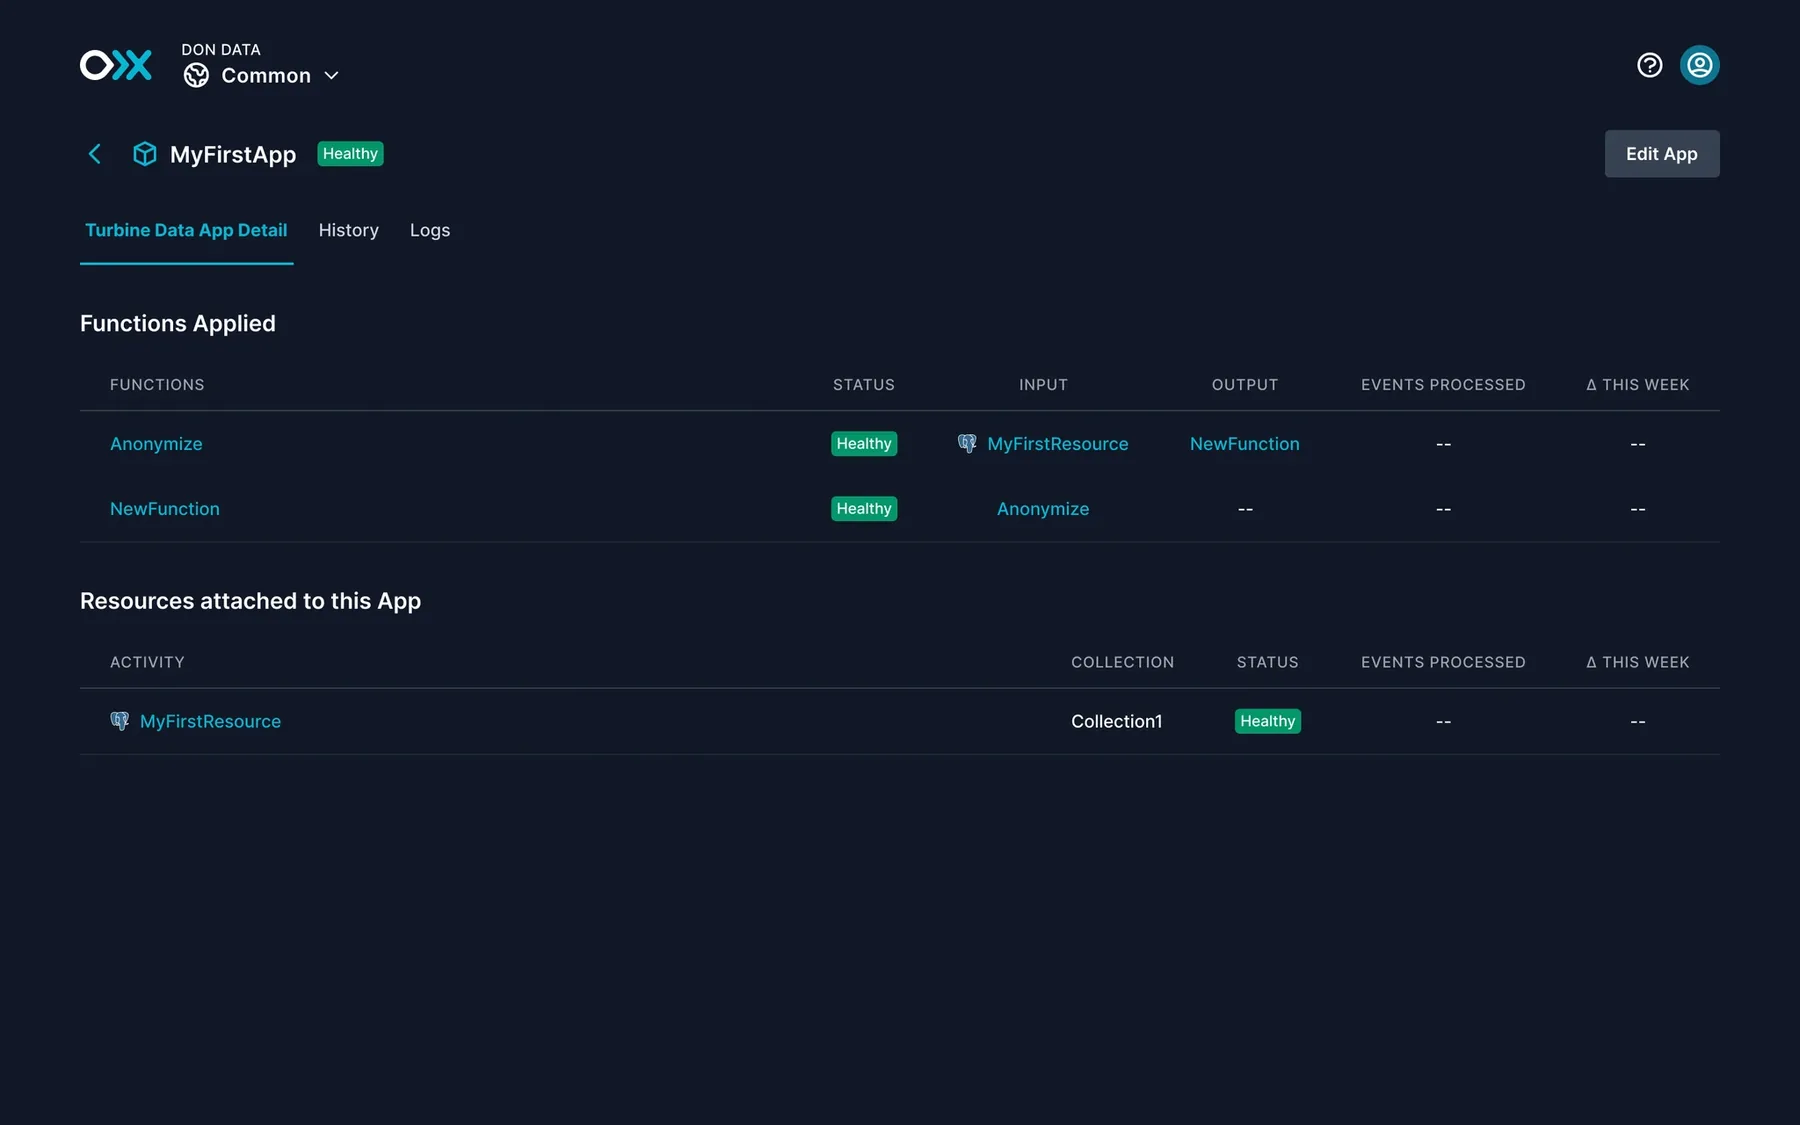
For production engineers, the primary objects are environments (where things run), apps (what's running), and logs (what's happening right now). Pipelines become an implementation detail inside an app.
Navigate by operational concern. "What's running in production and is anything wrong?" should be answerable from the home state with no drilling down required. That pushed environment health, app status, and recent log activity to the top level instead of burying them three screens deep inside a pipeline detail view.
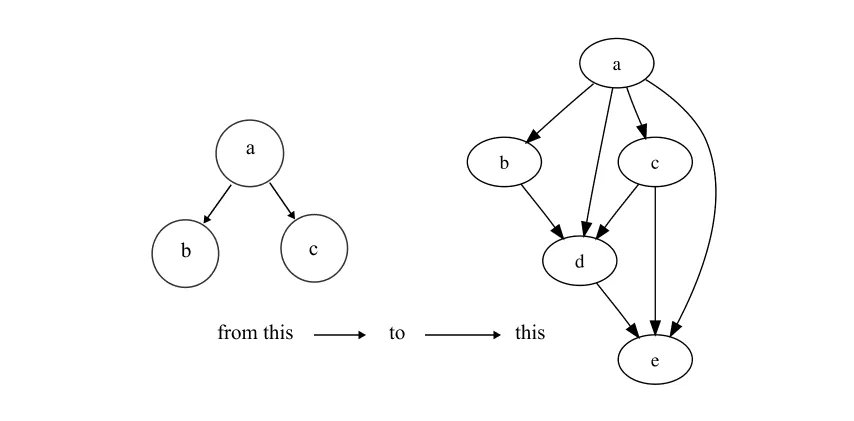
The DAG view was the most debated call internally. The concern: DAGs are harder to scan at a glance than linear flows. My position: the complexity was already there. We were just hiding it. Surfacing the real topology honestly — with good visual hierarchy and progressive disclosure for the details — was better than a simplified metaphor that would break down the first time an engineer encountered a real production setup. Engineers don't want you to lie to them about how their system works.
06Observability: the feature that wasn't really a feature
Early in research I asked every production engineer the same question: what do you do when something breaks in a data stream? Same answer every time. Open terminal, pull logs, grep for errors, cross-reference with another service, hope the relevant event is still in the window. Fragmented, slow, and often requiring escalated permissions just to see anything useful.
Charts tell you something broke. Logs tell you what broke and why. When you're in an incident, you don't pull up a graph to understand it — you go straight to the logs. Building metrics-first would have looked complete on a roadmap and been useless under pressure.
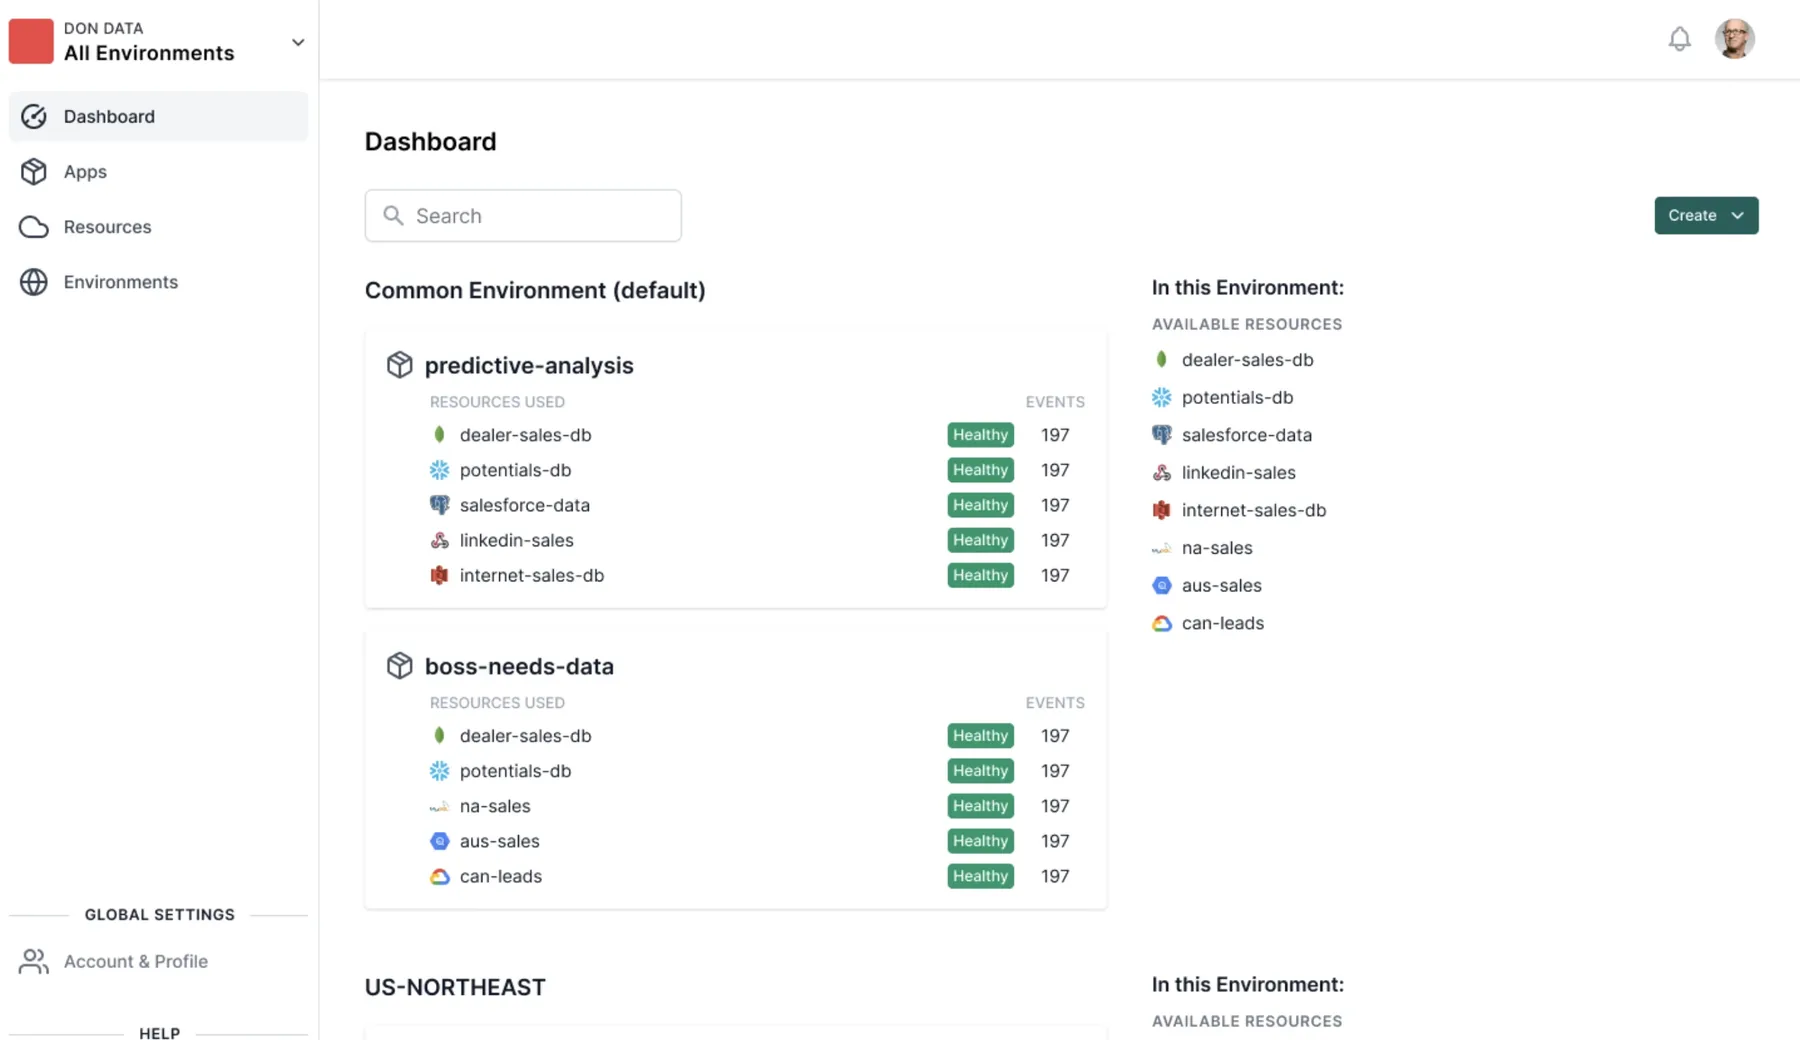 Observability dashboard, an iteration
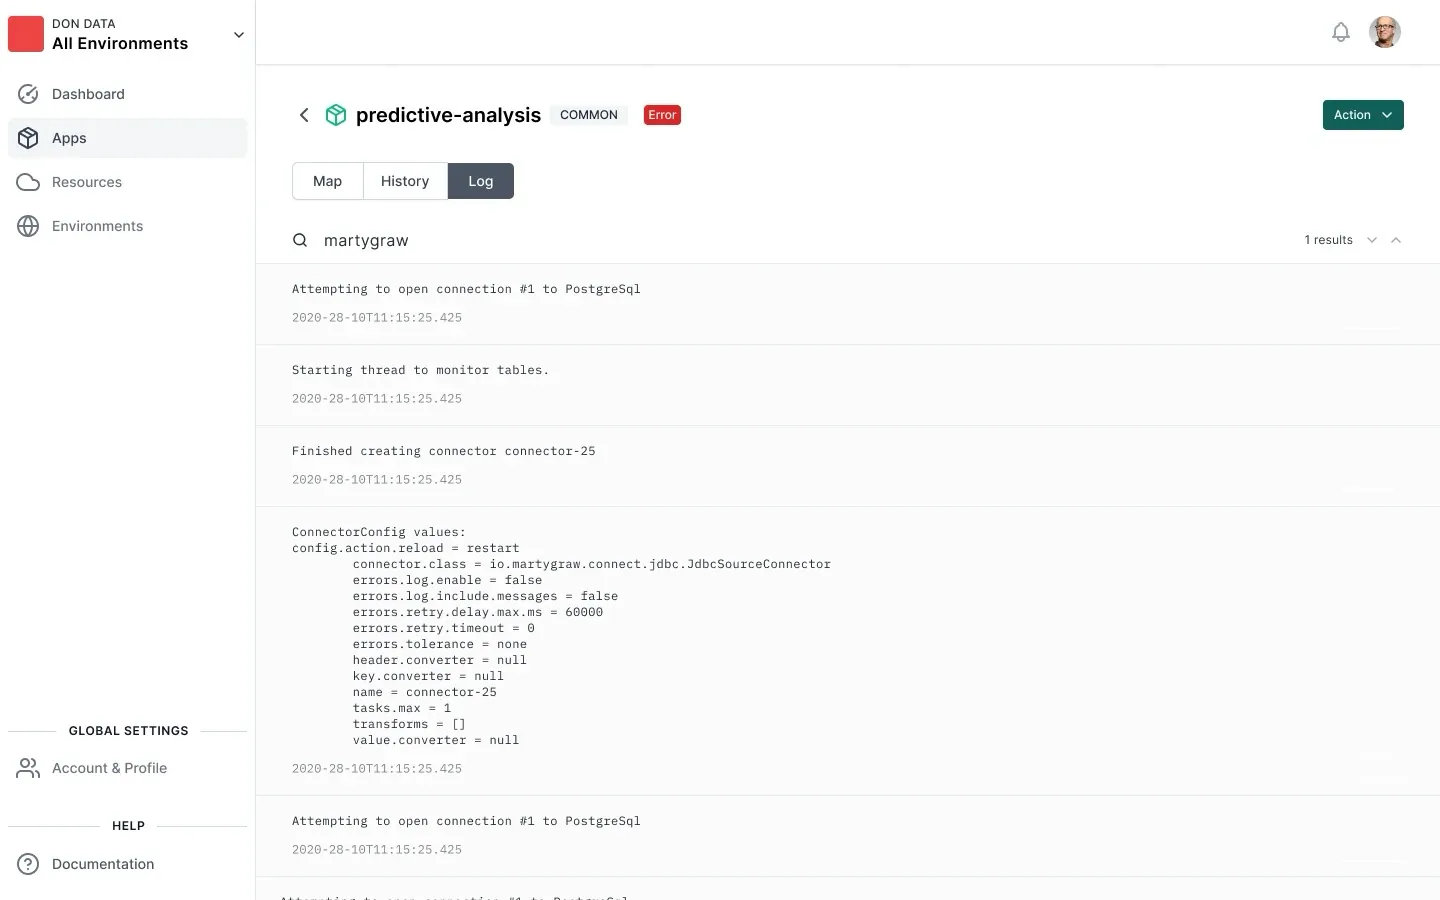 Log explorer
07The enterprise problem nobody told us about
The first enterprise deals surfaced a requirement we hadn't designed for: real organizational structure. Solo developers can share one environment. A team of 20 engineers with dev, staging, and production cannot. They need isolation, role-based access, and a way for team leads to see across all environments without drowning in noise.
We'd built assuming one environment per user. Enterprise reality was three to five environments per team with overlapping ownership. The hard design problem wasn't the technical model — engineering had that mostly figured out. It was the mental model question: how does a user know which environment they're in before they touch anything? A mis-deploy to production instead of staging isn't recoverable.
Persistent environment context in the top nav. The modal approach was cleaner and kept less visual clutter in the main UI. But it put environment context one click away rather than always visible. For a mistake with that severity, one click away isn't good enough. The nav stays slightly noisier. The user always knows where they are. Right tradeoff.
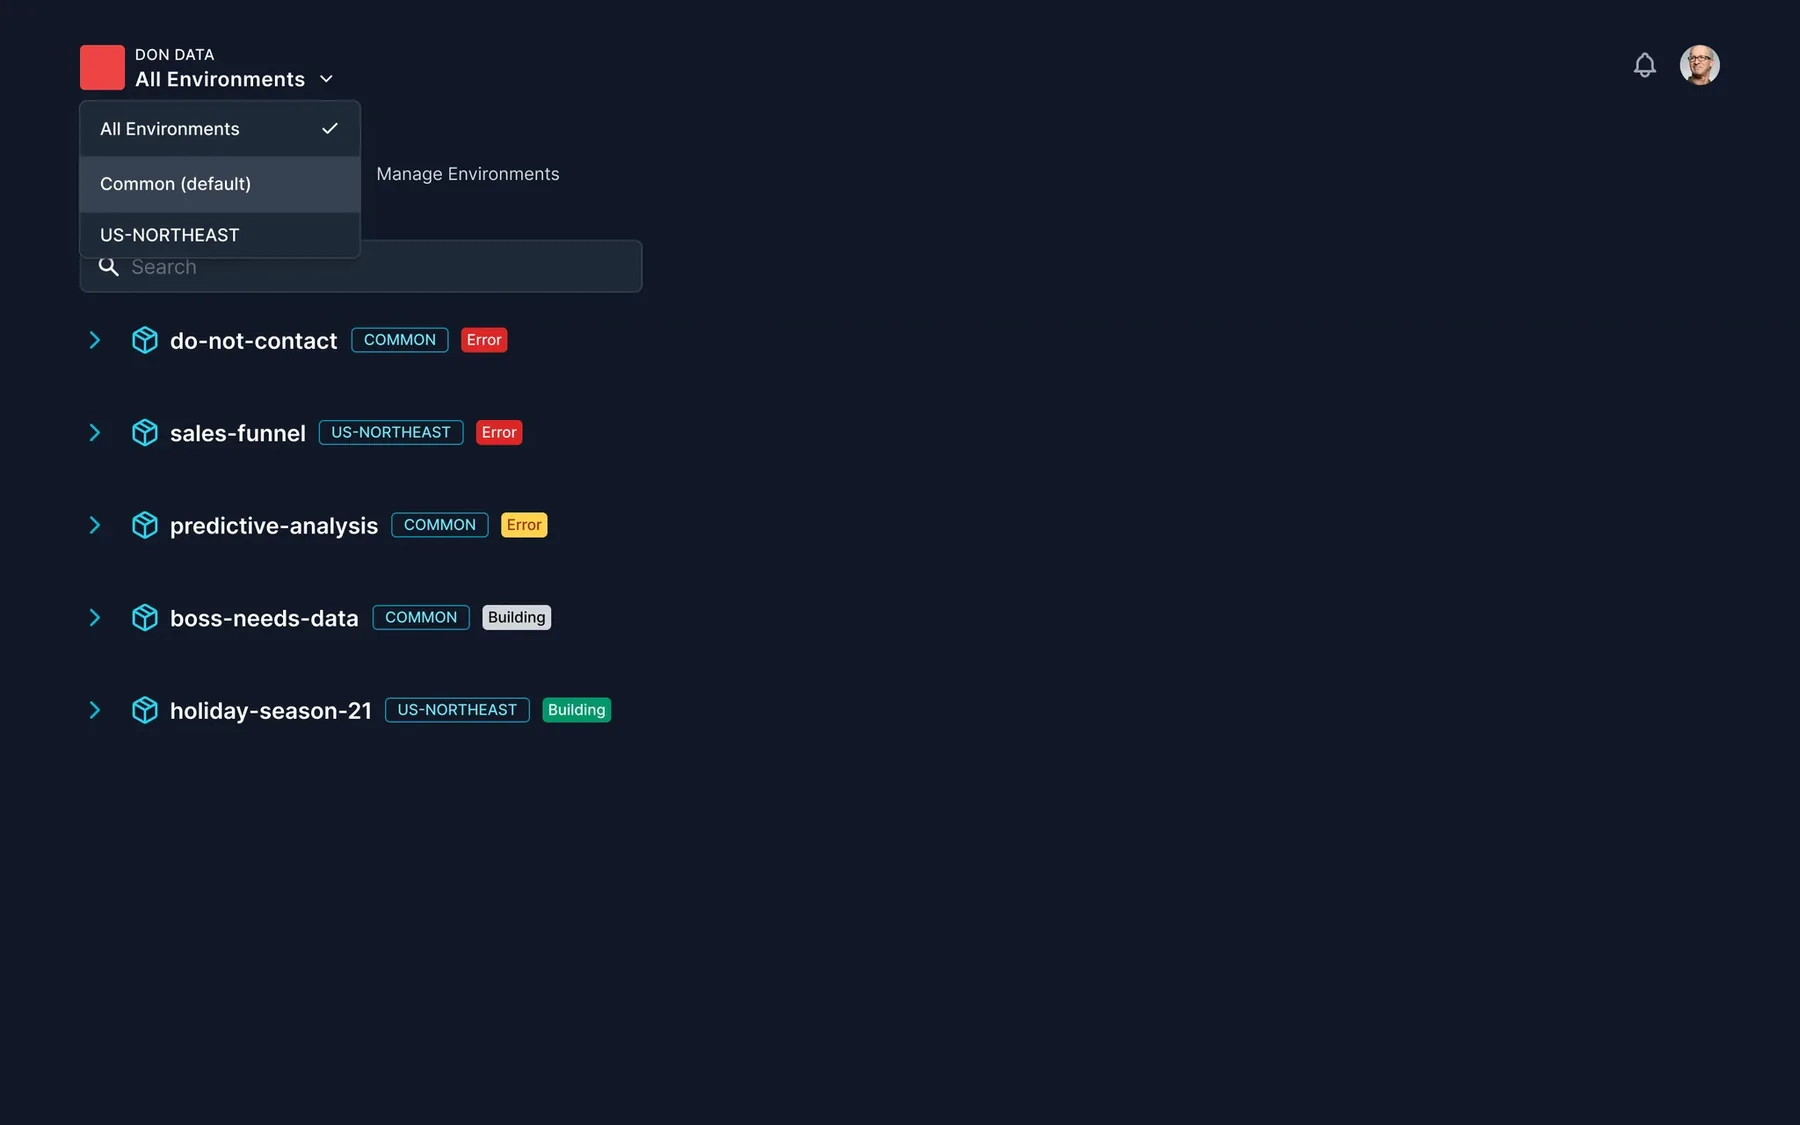 Environment selection
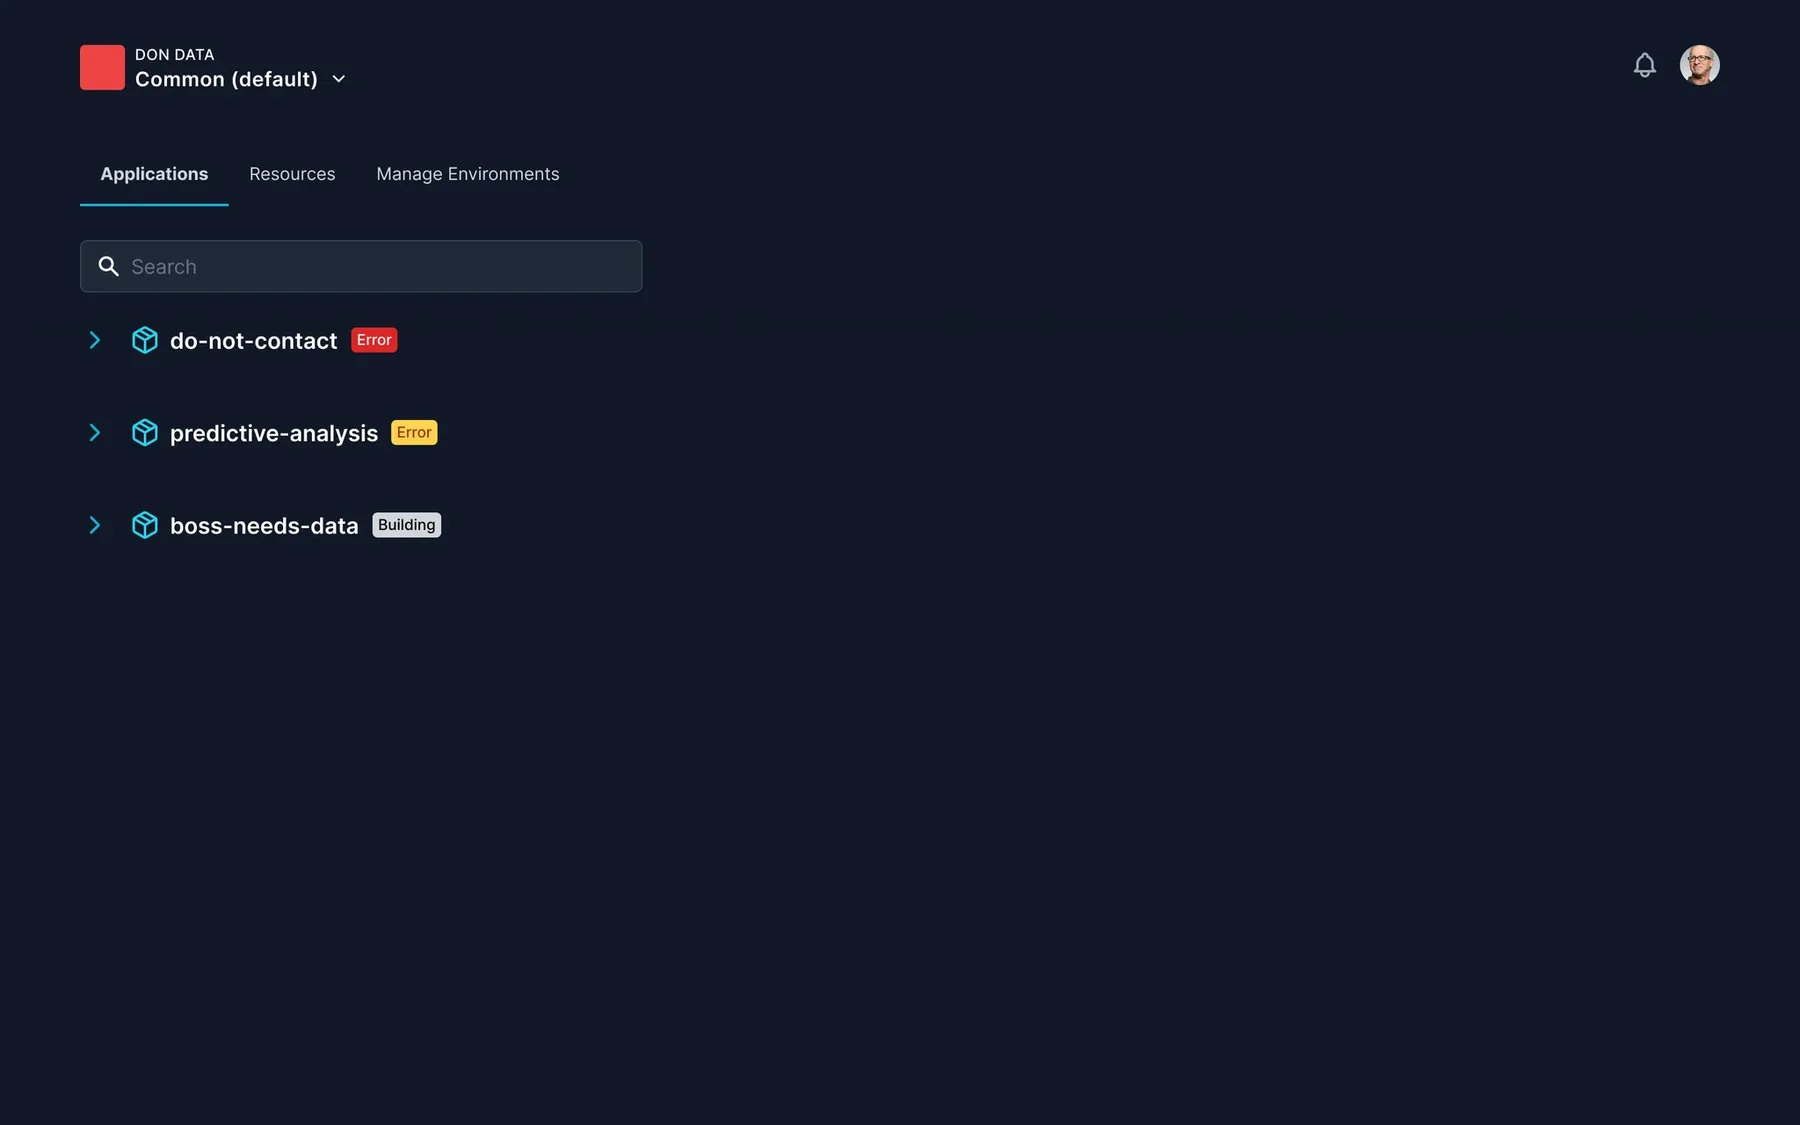 Common environment selected
08Design system as the thing that kept us from falling apart
The pivot compressed everything. We were redesigning core IA, building new interaction patterns, and supporting a completely different user mental model — simultaneously, with a small team, on a startup timeline.
The Yoshi design system work wasn't a separate track. It was what kept the pace from collapsing into chaos. Component patterns for log display, environment switching, and DAG visualization got built once and reused across every new surface. Without those building blocks, every screen would have required from-scratch decisions about density, type scale, and information hierarchy.
The tradeoff I navigated: velocity vs. consistency. Under pressure the temptation is to one-off components — ship something that works for this screen right now and reconcile later. I pushed against that every time, because "later" almost never comes at an early-stage startup, and a fragmented component library accrues design debt faster than anything else. Slightly more time on each component upfront meant every subsequent screen moved faster. That math is always right.
09What the numbers actually mean
10What I'd do differently
The pivot worked. We were slower to it than we should have been.
The signal that the assumed market was wrong existed in early research. It was there in how users described their workflows and in the workarounds they'd already built. We spent several months improving the existing product experience before stepping back to ask whether we were building for the right person at all. That's a question that should be in the research cadence from day one — not just "are users happy" but "does the person using this match the person we designed for." Different question. Needs to be asked on purpose.
On observability specifically: I made the right call going log-first, but I made it two weeks too late. The metrics-first direction got design work before we killed it. If I'd done the job-level research before any scoping conversation started, I would have landed at log-first from the beginning. The lesson is simple and I've carried it since: understand the job before you touch the scope. Not during. Before.
This project wasn't about making the product more usable. It was about catching the moment when a research finding becomes a business decision and being ready to make that handoff clearly. That means being willing to say something uncomfortable and having enough strategic context to turn it into a path forward. The design that followed was only possible because that framing happened first. When research changes the direction of a company, that's the job at its highest level.